How to Read CSV Files in R: The Definitive Handbook
The `read.csv()` function in R remains the most direct path to unlocking tabular data stored in CSV files. Whether you're parsing sales records, scientific datasets, or log files, this operation forms the foundation of nearly every data-driven project in R. The function's simplicity belies its sophistication—understanding its parameters and edge cases transforms raw comma-separated data into structured R objects ready for analysis.
What separates competent data handling from expert-level workflows? It's not just executing `read.csv()` but mastering its nuances: specifying delimiters for non-standard files, managing encoding issues, and optimizing memory usage for large datasets. These details determine whether your analysis runs smoothly or stalls at the first hurdle.
The evolution of this function mirrors R's growth as a data science powerhouse. From its early days as a basic file reader to today's integration with modern data pipelines, `read.csv()` has become a cornerstone of reproducible research. Yet its potential remains underutilized—many users stick to default settings when advanced configurations could solve problems before they arise.
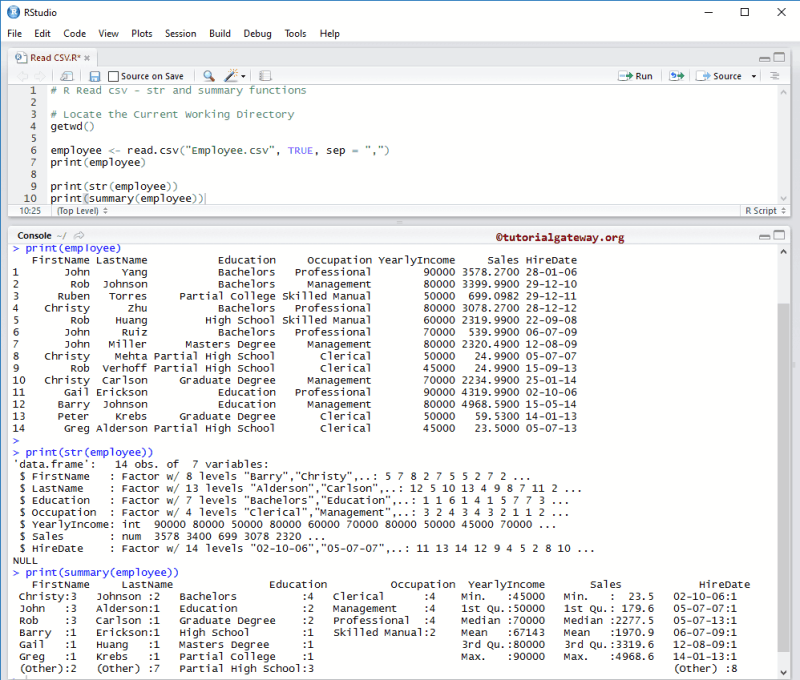
The Complete Overview of Reading CSV Files in R
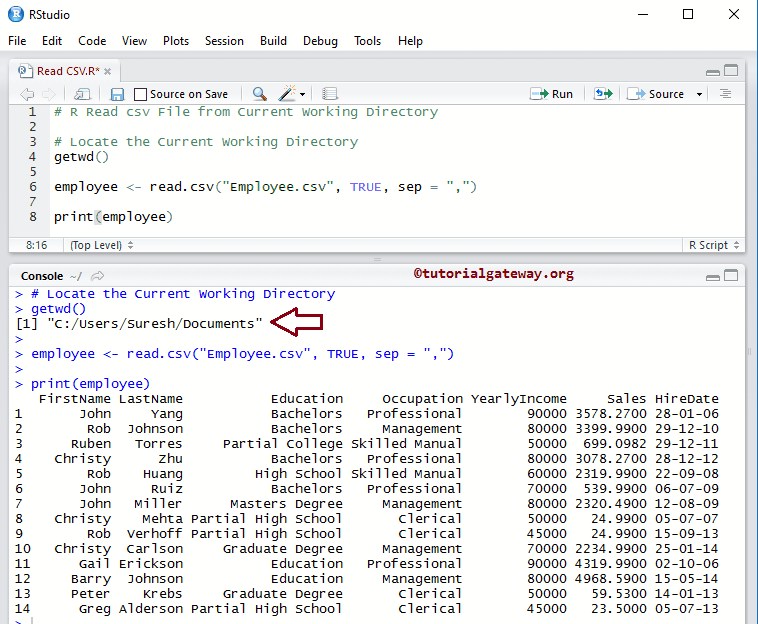
The `read.csv()` function serves as R's primary interface for importing CSV-formatted data, converting text files into data frames—R's native tabular structure. Its flexibility extends beyond standard CSV files to handle variations like tab-separated values (TSV) or other delimiters, making it indispensable for data integration tasks. The function's true power lies in its ability to parse complex file structures while providing control over data types, missing value representations, and file encoding.At its core, `read.csv()` implements a four-step process: file detection, header parsing, column assignment, and data type conversion. Each step offers customization options through parameters like `header`, `sep`, and `colClasses`. Understanding these parameters isn't just about fixing errors—it's about designing efficient data pipelines that minimize memory usage and processing time, particularly important when working with datasets exceeding system memory capacity.
Historical Background and Evolution
The concept of reading tabular data in R dates back to the language's early days in the 1990s, when data analysis often involved manual data entry or specialized statistical packages. The `read.csv()` function emerged as part of R's base utilities, providing a standardized way to import data from spreadsheets and databases—a critical feature as R gained popularity in academic and research circles.Over time, the function evolved alongside R's growing ecosystem. The introduction of the `data.table` package in 2006 demonstrated how alternative implementations could offer superior performance for large datasets, while the `readr` package from the tidyverse introduced more robust handling of file encodings and memory management. These developments didn't render `read.csv()` obsolete but rather expanded the toolkit available to data practitioners, each with distinct strengths depending on the use case.
Core Mechanisms: How It Works
When `read.csv()` executes, it first scans the file to determine its structure, including the number of columns and whether a header row exists. The function then processes each line sequentially, splitting values by the specified delimiter (defaulting to commas) and converting them to R's internal data types. This conversion is where potential issues arise—numeric fields containing non-numeric characters, for example, may trigger warnings or errors if not properly handled.Table of Contents
- The Complete Overview of Reading CSV Files in R
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What happens if my CSV file uses a different delimiter than commas?
- Q: How can I handle files with mixed data types in columns?
- Q: Why does my CSV import fail with "invalid 'factor' level" errors?
- Q: What's the most memory-efficient way to read large CSV files?
- Q: How do I handle encoding issues when reading CSV files?
- Q: Can I read CSV files directly from URLs in R?
- Q: What's the difference between `read.csv()` and `read.csv2()`?
- Q: How do I skip rows or columns during CSV import?
- Q: Why does my CSV import take so long with large files?
- Q: How can I preserve the original column names from a CSV file?
The function's memory management becomes particularly critical with large files. By default, `read.csv()` loads the entire dataset into memory, which can be problematic for files exceeding system capacity. Advanced users mitigate this by using parameters like `nrows` for partial reads or by leveraging alternative packages that implement more efficient memory handling strategies, such as `data.table::fread()` or `readr::read_csv()`.
Key Benefits and Crucial Impact
The ability to seamlessly import CSV files in R transforms raw data into actionable insights, bridging the gap between data collection and analysis. This capability is particularly valuable in fields where data is frequently exported from external systems—financial reporting, scientific experiments, or customer relationship management—where CSV remains the universal exchange format.Beyond basic data import, the function's flexibility enables handling of real-world data challenges: inconsistent delimiters, mixed data types, and encoding issues that would otherwise derail analysis. These capabilities make `read.csv()` more than a utility function—it's a critical component of reproducible data workflows that can be documented, shared, and automated.
"Data cleaning is where the magic happens—but you can't clean what you can't read. The ability to reliably import CSV files is the first step in turning messy data into meaningful analysis."
— Hadley Wickham, creator of the tidyverse
Major Advantages
- Universal Compatibility: Handles virtually any CSV-formatted file, including those with non-standard delimiters or quoted fields, through parameters like `sep` and `quote`.
- Data Type Control: The `colClasses` parameter allows explicit specification of column data types, preventing automatic type conversion errors common with mixed-content files.
- Memory Efficiency Options: Parameters like `nrows` and `skip` enable processing of large files in chunks, while `stringsAsFactors` (now deprecated) controlled factor conversion behavior.
- Encoding Support: The `fileEncoding` parameter addresses character encoding issues common when importing files created in different locales or systems.
- Integration with R Ecosystem: Works seamlessly with other R functions and packages, including `dplyr` for data manipulation and `ggplot2` for visualization, creating cohesive analysis pipelines.
Comparative Analysis
| Feature | read.csv() | readr::read_csv() | data.table::fread() |
|---|---|---|---|
| Memory Efficiency | Moderate (loads entire file) | High (streaming processing) | Very High (optimized for large files) |
| Encoding Handling | Basic (fileEncoding) | Advanced (locale support) | Comprehensive (auto-detection) |
| Performance with Large Files | Slower (full memory load) | Faster (chunked processing) | Fastest (parallel processing) |
| Parameter Flexibility | Moderate (basic options) | High (column type specification) | Very High (custom parsing rules) |
Future Trends and Innovations
The landscape of CSV file handling in R continues to evolve, with emerging trends focused on performance optimization and integration with modern data infrastructure. The `readr` package's emphasis on streaming processing represents a significant advancement, particularly for datasets that exceed available memory. Future developments may further blur the lines between traditional CSV processing and big data frameworks, with R packages increasingly supporting distributed computing environments.Another key trend is the growing importance of data validation during import. As datasets become more complex, there's increasing demand for functions that not only read but also validate data integrity—detecting missing values, type inconsistencies, or structural anomalies before they affect downstream analysis. These capabilities will likely become standard features in next-generation CSV reading functions, further reducing the manual effort required for data preparation.

Conclusion
Mastering the `read.csv()` function in R is about more than basic file import—it's about understanding the complete data pipeline from raw file to analyzed results. The function's parameters offer precise control over data parsing, making it adaptable to virtually any CSV file scenario. However, recognizing when to use alternatives like `readr` or `data.table` is equally important, particularly when dealing with large or complex datasets.For data practitioners, this means moving beyond default settings to configure imports that match specific project requirements. Whether optimizing for speed, memory efficiency, or data integrity, the right approach to reading CSV files in R can mean the difference between a smooth analysis workflow and one plagued by errors and inefficiencies.
Comprehensive FAQs
Q: What happens if my CSV file uses a different delimiter than commas?
A: Use the `sep` parameter to specify the delimiter. For tab-separated files, set `sep = "\t"`. For semicolons, use `sep = ";"`. Always test with a small subset of data first to verify correct parsing.
Q: How can I handle files with mixed data types in columns?
A: Specify column data types using the `colClasses` parameter. For example, `colClasses = c("numeric", "character", "Date")` forces specific types. Alternatively, use `readr::read_csv()` which handles type inference more robustly.
Q: Why does my CSV import fail with "invalid 'factor' level" errors?
A: This occurs when character columns contain unexpected values. Either pre-process the file to standardize values, or use `stringsAsFactors = FALSE` (default in newer R versions) to keep columns as character vectors.
Q: What's the most memory-efficient way to read large CSV files?
A: Use `data.table::fread()` for fastest performance or `readr::read_csv()` for streaming processing. For base R, read in chunks with `nrows` or process files line-by-line using `readLines()` with custom parsing.
Q: How do I handle encoding issues when reading CSV files?
A: Specify the encoding with `fileEncoding = "UTF-8"` or other appropriate encodings like "latin1". For automatic detection, use `readr::read_csv()` which handles encoding more intelligently.
Q: Can I read CSV files directly from URLs in R?
A: Yes, use `url = "file_url"` parameter in `read.csv()` or `readr::read_csv()`. For large files, consider downloading first with `download.file()` then reading locally.
Q: What's the difference between `read.csv()` and `read.csv2()`?
A: `read.csv2()` is optimized for European-style CSV files where decimals use commas and thousands use periods. It automatically adjusts these formats during import.
Q: How do I skip rows or columns during CSV import?
A: Use `skip` to ignore initial rows and `colClasses` with `NA` to exclude columns. For selective column loading, specify column names in `colClasses` or use `readr::read_csv()` with `col_select()`.
Q: Why does my CSV import take so long with large files?
A: Base R loads entire files into memory. For faster processing, use `data.table::fread()` (optimized C code) or `readr::read_csv()` (streaming approach). Consider compressing files if storage is an option.
Q: How can I preserve the original column names from a CSV file?
A: Set `check.names = FALSE` to prevent R from automatically modifying column names. For files without headers, use `header = TRUE` and provide your own names via `col.names`.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.