How to Seamlessly Bring CSV Dataframe R Into Your Workflow
The transition from raw CSV files to actionable insights in R begins with a single, often overlooked step: bringing the CSV dataframe into R. This process is the foundation of nearly every data analysis pipeline, yet its nuances—from file path handling to encoding quirks—can silently derail projects. Whether you're pulling transaction logs, survey responses, or scientific measurements, the method you choose to import a CSV into an R dataframe determines how smoothly your analysis will proceed. Missteps here cascade into corrupted datasets, wasted hours debugging, or even flawed conclusions.
The most common pitfall isn’t technical—it’s conceptual. Many assume that `read.csv()` is a one-size-fits-all solution, but in reality, CSV files arrive in countless formats: some with embedded commas in quoted fields, others using semicolons as delimiters, and many more with headers on row 3 instead of row 1. R’s flexibility in handling CSV dataframes is unmatched, but only if you understand the underlying mechanics. A well-structured dataframe in R isn’t just a table; it’s a living object that will feed into visualizations, statistical models, and machine learning algorithms. Ignore the import phase, and you risk starting your analysis on shaky ground.
For teams working with large-scale datasets, the stakes are higher. A poorly optimized import can turn a 10-minute task into an hour-long bottleneck, especially when dealing with files exceeding 1GB. Modern R packages like `data.table` or `readr` from the tidyverse offer performance advantages, but their trade-offs—such as memory efficiency versus ease of use—must be weighed carefully. The goal isn’t just to bring a CSV into R, but to do so in a way that aligns with your project’s scale, speed requirements, and long-term maintainability.

The Complete Overview of Bringing CSV Dataframe R
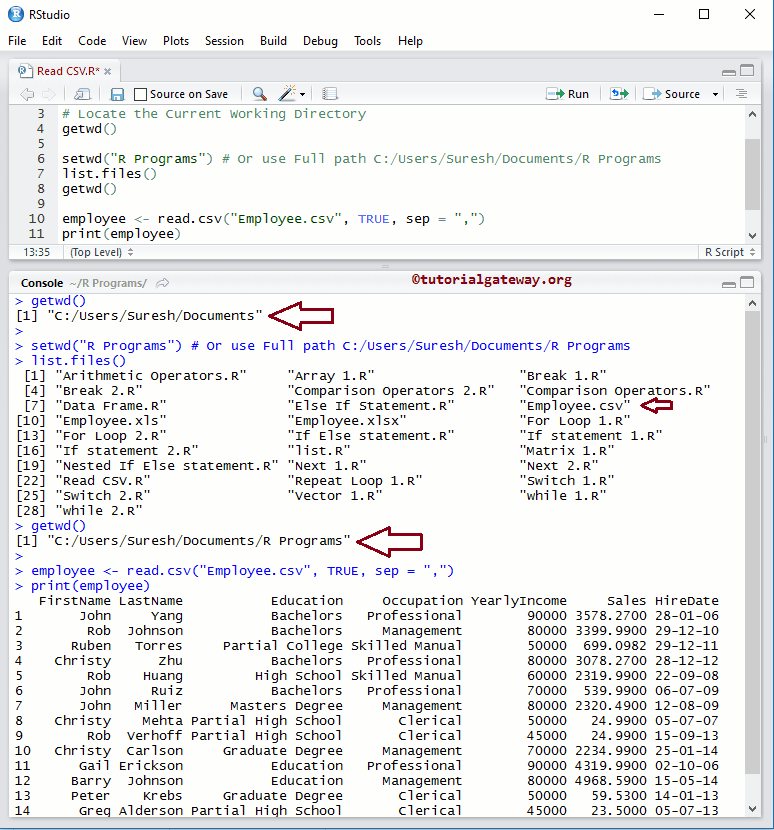
At its core, importing a CSV into R is a bridge between human-readable data and computational analysis. R’s ecosystem provides multiple pathways to achieve this, each catering to different needs: base R functions for simplicity, `tidyverse` tools for consistency, and specialized packages for high-performance scenarios. The choice often hinges on whether you prioritize readability, speed, or integration with other workflows. For instance, `read.csv()` from base R is familiar to veterans but lacks optimizations for modern hardware, while `read_csv()` from the `readr` package (part of the tidyverse) prioritizes parsing efficiency and consistent behavior across file types.The real complexity lies in the hidden layers beneath the surface. CSV files are deceptively simple—they appear as plain text, but their structure can be riddled with inconsistencies. Fields may be enclosed in single or double quotes, delimiters might vary by region (commas in the US, semicolons in Europe), and line endings can differ between operating systems. R’s import functions must decode these nuances without collapsing the dataframe’s integrity. Advanced users often customize these imports with arguments like `sep`, `colClasses`, or `na.strings` to preemptively handle edge cases, but even these require a deep understanding of how R interprets character vectors and numeric types.
Historical Background and Evolution
The CSV format itself emerged in the 1970s as a lightweight alternative to proprietary database exports, but its adoption in R mirrors the language’s broader evolution. Early versions of R relied on `scan()` and manual parsing for CSV files, a process that was both error-prone and time-consuming. The introduction of `read.csv()` in the late 1990s marked a turning point, offering a standardized way to bring CSV data into R with minimal fuss. However, this function was built with simplicity in mind, not performance—leading to inefficiencies when processing large datasets.The tide turned in the 2010s with the rise of the tidyverse, a collection of packages designed for seamless data manipulation. Hadley Wickham’s `readr` package, released in 2014, revolutionized CSV imports by leveraging C++ for faster parsing and introducing features like automatic type detection. This shift reflected a broader trend: as data volumes grew, so did the demand for tools that could handle CSV dataframe R operations without sacrificing clarity. Today, alternatives like `data.table::fread()` and `readxl` for Excel files coexist, each serving niche use cases where traditional methods fall short.
Core Mechanisms: How It Works
Under the hood, R’s CSV import functions perform a series of transformations that convert raw text into a structured dataframe. The process begins with reading the file line by line, splitting each line into columns based on the delimiter, and then coercing each column into the appropriate R data type (e.g., `integer`, `character`, or `factor`). This is where subtle issues arise: a column labeled "age" might be read as a character vector if the CSV contains non-numeric entries like "N/A," forcing users to manually convert it with `as.numeric()` later.Table of Contents
- The Complete Overview of Bringing CSV Dataframe R
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the fastest way to bring a large CSV into R?
- Q: How do I handle a CSV with irregular delimiters, like tabs or pipes?
- Q: Why does R convert my numeric columns to characters when importing a CSV?
- Q: Can I skip rows or columns when bringing a CSV into R?
- Q: How do I ensure my CSV import is reproducible across different machines?
- Q: What should I do if my CSV has embedded line breaks within quoted fields?
Performance optimizations, such as those in `readr`, skip unnecessary steps like checking for `NA` values until the entire file is parsed, reducing overhead. For very large files, these packages also employ memory-mapped files to avoid loading the entire dataset into RAM at once. Understanding these mechanics is critical when working with CSV dataframes in R, as it allows you to anticipate bottlenecks and choose the right tool for the job. For example, `data.table::fread()` excels at handling files with millions of rows by processing them in chunks, while `read_csv()` prioritizes user-friendly defaults.
Key Benefits and Crucial Impact
The ability to efficiently bring CSV data into R is more than a technical skill—it’s a gateway to reproducible research and scalable analysis. In industries like finance, healthcare, and logistics, where data-driven decisions are paramount, the reliability of this process directly impacts outcomes. A well-imported CSV dataframe ensures that downstream analyses—whether linear regressions, clustering algorithms, or interactive dashboards—operate on clean, consistent data. Without this foundation, even the most sophisticated models risk producing misleading results due to silent errors in the import phase.For collaborative teams, standardized CSV import workflows reduce the "it works on my machine" problem. When every analyst uses the same method to load CSV into R, discrepancies between environments shrink, and debugging becomes more predictable. This consistency extends to version control: documenting import parameters (e.g., `encoding = "UTF-8"`, `stringsAsFactors = FALSE`) ensures that future team members can replicate the exact same dataframe structure.
"The first 10% of coding is 90% of the effort—especially when it comes to data import. Get this right, and the rest of your analysis flows effortlessly." — Hadley Wickham, Chief Scientist at RStudio
Major Advantages
- Flexibility in File Handling: R supports CSV imports from local files, URLs, or even compressed archives (e.g., `.gz` files), making it adaptable to diverse data sources.
- Automatic Type Detection: Modern packages like `readr` infer column types dynamically, reducing manual intervention and minimizing errors from misclassified data.
- Memory Efficiency: Functions like `fread()` and `read_csv()` are designed to handle large files by processing data in chunks, avoiding memory overload.
- Integration with the Tidyverse: Once a CSV is loaded into R as a dataframe, it seamlessly integrates with `dplyr`, `ggplot2`, and other tidyverse tools for further analysis.
- Customization for Edge Cases: Advanced users can specify custom delimiters, handle malformed rows, or even parse nested CSV structures (e.g., JSON-like data embedded in cells).

Comparative Analysis
| Method | Best Use Case |
|---|---|
base::read.csv() |
Small to medium files where simplicity and compatibility are prioritized over speed. |
readr::read_csv() |
Large files or projects using the tidyverse, where parsing speed and consistency matter. |
data.table::fread() |
Extremely large files (100MB+) requiring fast, memory-efficient imports. |
readxl::read_excel() |
Excel files or CSV-like data with complex formatting (e.g., merged cells). |
Future Trends and Innovations
The future of CSV dataframe R integration is likely to focus on two fronts: automation and interoperability. As AI-driven data pipelines become more prevalent, tools that can auto-detect and clean CSV files during import—without manual scripting—will gain traction. Projects like R’s `arrow` package, which enables lazy loading of large datasets, hint at this direction, allowing analysts to work with subsets of data without full imports.On the interoperability front, expect tighter integration between R and cloud storage systems (e.g., AWS S3, Google BigQuery). Packages like `s3fs` already enable direct CSV imports from cloud buckets, but future iterations may include built-in compression/decompression and schema validation. For teams working with CSV dataframes in R, these advancements will blur the line between local analysis and distributed computing, making it easier to scale workflows without rewriting code.
Conclusion
Mastering the art of bringing CSV data into R is not just about executing a single function—it’s about understanding the ecosystem that surrounds it. From choosing the right package for your file size to anticipating encoding pitfalls, each decision shapes the quality of your analysis. The tools available today are more powerful than ever, but their effectiveness hinges on how thoughtfully they’re applied.For beginners, start with `readr::read_csv()` for its balance of speed and usability. For power users, explore `data.table` or `arrow` when performance is critical. Regardless of your path, document your import parameters and validate your data early. The time spent refining this foundational step will pay dividends in accuracy, reproducibility, and efficiency—ensuring that your CSV dataframe in R becomes the robust building block it’s meant to be.
Comprehensive FAQs
Q: What’s the fastest way to bring a large CSV into R?
A: For files over 100MB, use data.table::fread() or readr::read_csv() with the col_types argument pre-specified to skip type inference. Both methods process data in chunks, minimizing memory usage. If working with compressed files (e.g., `.csv.gz`), pipe the file directly into R using gzfile() with read.csv().
Q: How do I handle a CSV with irregular delimiters, like tabs or pipes?
A: Specify the delimiter using the sep argument. For example, read.csv("file.csv", sep = "\t") for tab-delimited files or sep = "|" for pipes. If the delimiter is embedded in quoted fields, use readr::read_delim() with escape_double = FALSE or escape_single = FALSE to control parsing behavior.
Q: Why does R convert my numeric columns to characters when importing a CSV?
A: This typically happens when the CSV contains non-numeric entries (e.g., "N/A", "missing") or improper formatting (e.g., commas as decimal separators in non-English locales). Use colClasses in base R or col_types in readr to enforce types, or preprocess the CSV with gsub() to replace problematic values before importing. For example: read.csv("file.csv", colClasses = "numeric").
Q: Can I skip rows or columns when bringing a CSV into R?
A: Yes. Use skip to ignore the first n rows (e.g., skip = 3 for headers on row 4) and col_select() from dplyr to filter columns after import. For readr, use skip = 3 directly in read_csv(), or pipe the result into select() for column selection.
Q: How do I ensure my CSV import is reproducible across different machines?
A: Document all import parameters, including encoding (e.g., "UTF-8"), stringsAsFactors (FALSE for consistency), and locale settings (e.g., locale = locale(decimal_mark = ",") for European data). Store these parameters in a script or config file to ensure identical imports. Tools like here::here() also help standardize file paths.
Q: What should I do if my CSV has embedded line breaks within quoted fields?
A: Use readr::read_csv() with comment = "" and quote = "" to disable automatic line break handling, then manually split the column post-import using stringr::str_split() or regex. Alternatively, preprocess the CSV with a tool like dos2unix to normalize line endings before importing.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.