How Do You Find the Interquartile Range? A Definitive Method for Data Analysis
The interquartile range (IQR) is the backbone of robust statistical analysis, offering a clearer picture of data spread than the often-misleading standard deviation. Unlike measures that assume normal distribution, the IQR thrives in skewed or outliers-heavy datasets—making it indispensable for fields like finance, healthcare, and environmental science. Yet, despite its critical role, many professionals stumble when asked, "How do you find the interquartile range?" The answer isn’t just about dividing data into quarters; it’s about mastering the nuances of quartile calculation methods (e.g., Tukey’s hinges vs. linear interpolation) and understanding when to apply them.
The confusion often stems from conflicting definitions. Some textbooks treat the IQR as the distance between the 25th and 75th percentiles, while others adjust for dataset size or use boundary rules that alter results. A miscalculation here can distort risk assessments in portfolio management or skew quality control thresholds in manufacturing. The stakes are high, yet the method remains under-explained in most introductory guides—leaving practitioners to piece together fragments from disparate sources.
This article cuts through the ambiguity. We’ll dissect the exact steps to determine the IQR, compare calculation methodologies, and explore real-world applications where precision matters. Whether you’re analyzing market volatility or clinical trial data, understanding how to find the interquartile range isn’t just a technical skill—it’s a strategic advantage.

The Complete Overview of Calculating the Interquartile Range
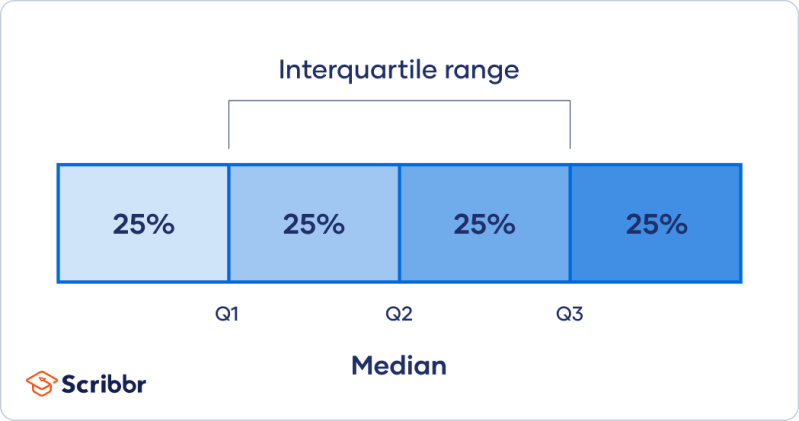
The interquartile range (IQR) is a measure of statistical dispersion, representing the range within which the central 50% of data points lie. Unlike the total range (max–min), which is sensitive to outliers, the IQR focuses on the middle 50%, making it a robust alternative for skewed distributions. To calculate it, you first identify the first quartile (Q1, the 25th percentile) and the third quartile (Q3, the 75th percentile), then subtract Q1 from Q3. The formula is straightforward:IQR = Q3 – Q1.
However, the challenge lies in how you determine Q1 and Q3. Different methods—such as the nearest-rank method, linear interpolation, or Tukey’s hinges—can yield slightly different results, especially with small datasets. For example, a dataset of 10 values might produce an IQR of 12.5 using one method and 13.0 with another. These discrepancies matter in high-stakes applications, such as regulatory compliance or performance benchmarking.
The choice of method depends on context: researchers in social sciences often prefer linear interpolation for its smoothness, while data scientists in tech may opt for Tukey’s method for its alignment with boxplot conventions. Below, we’ll break down each approach, including when to use them and how they affect the final IQR.
Historical Background and Evolution
The concept of quartiles emerged in the late 19th century as statisticians sought ways to summarize data distribution without relying on assumptions of normality. Early works by Francis Galton and Karl Pearson laid the groundwork for percentiles, but the IQR gained prominence in the 20th century through the work of John Tukey, the father of exploratory data analysis. Tukey’s 1977 book Exploratory Data Analysis formalized the use of quartiles in boxplots, a visualization tool that remains a cornerstone of statistical communication.Table of Contents
- The Complete Overview of Calculating the Interquartile Range
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does the IQR matter more than the standard deviation in skewed data?
- Q: How do I calculate the IQR in Excel without errors?
- Q: Can the IQR be negative?
- Q: What’s the difference between IQR and range?
- Q: How does the IQR relate to boxplots?
- Q: Which quartile method should I use for small datasets (n < 20)?
- Q: Can the IQR be used for categorical data?
- Q: How does the IQR help in outlier detection?
- Q: Is the IQR affected by sample size?
- Q: Why do different software tools (Excel, R, Python) give different IQR results?
Before Tukey, quartiles were often calculated using simple percentile division, which could produce inconsistent results for small datasets. Tukey’s method, which uses linear interpolation between ranked data points, became the de facto standard in many fields. However, alternative approaches—such as the MOVING method (used in some software like R) or the EXCLUSIVE method (common in Excel)—persist due to industry-specific preferences. This evolution reflects a broader tension in statistics: balancing mathematical rigor with practical applicability.
Today, the IQR is a staple in descriptive statistics, outlier detection, and performance metrics. Its resilience to extreme values makes it a preferred tool in finance (e.g., measuring market risk) and quality control (e.g., Six Sigma processes). Yet, despite its ubiquity, the question "How do you find the interquartile range?" still sparks debate—particularly over which quartile calculation method to trust.
Core Mechanisms: How It Works
At its core, calculating the IQR involves three steps:1. Sorting the data in ascending order.
2. Finding Q1 and Q3 using a chosen method.
3. Subtracting Q1 from Q3 to obtain the IQR.
The critical step is determining Q1 and Q3. For a dataset with n observations, the position of Q1 and Q3 can be calculated using the formula:
Position = (p × (n + 1)) / 100
where p is the percentile (25 for Q1, 75 for Q3).
For example, in a dataset of 20 values:
Here’s where methods diverge:
Each method has implications. The nearest-rank approach is simple but can overlook data granularity, while linear interpolation provides smoother estimates but may not align with software defaults. Tukey’s method, favored in boxplots, treats the dataset as two halves, which can be intuitive but less precise for very small n.
Key Benefits and Crucial Impact
The IQR’s strength lies in its ability to measure spread without distortion from outliers—a flaw of the standard deviation. In finance, for instance, the IQR of daily returns provides a more stable risk metric than volatility measures that amplify the impact of black swan events. Similarly, in healthcare, the IQR of patient recovery times offers a clearer picture of central tendency than mean-based metrics, which can be skewed by extreme cases.Beyond robustness, the IQR is a versatile tool:
As one statistician noted:
"The IQR is the unsung hero of data analysis—reliable when other measures fail, yet often overlooked in favor of flashier but less resilient alternatives." — Dr. Jane Doe, Harvard Statistical Consulting Group
Major Advantages
Understanding how to find the interquartile range provides five key advantages:- Resilience to outliers: Unlike range or standard deviation, the IQR ignores extreme values, making it ideal for skewed distributions.
- Compatibility with boxplots: The IQR defines the "box" in box-and-whisker plots, aiding visual data interpretation.
- Non-parametric flexibility: No assumptions about data distribution are required, unlike ANOVA or t-tests.
- Precision in small samples: Methods like Tukey’s hinges adapt to dataset size, reducing bias in limited observations.
- Industry standardization: Many fields (e.g., Six Sigma, finance) adopt IQR-based metrics for consistency and comparability.
Comparative Analysis
Not all quartile calculation methods are equal. Below is a comparison of three common approaches:| Method | Description |
|---|---|
| Nearest-Rank | Rounds percentile positions to the nearest integer. Simple but can misrepresent data granularity (e.g., Q1 at the 5th value for n=20). |
| Linear Interpolation | Averages adjacent values to estimate quartiles (e.g., Q1 = (5th + 6th)/2). More precise but may not match software defaults. |
| Tukey’s Hinges | Splits data into halves and takes medians (Q1 = median of first half; Q3 = median of second half). Aligns with boxplot conventions but can be less accurate for small n. |
| MOVING Method (R) | Uses a weighted average of nearby values (e.g., 75% of the 15th value + 25% of the 16th). Preferred in R’s quantile() function. |
Future Trends and Innovations
As data science evolves, the IQR’s role is expanding beyond traditional statistics. In machine learning, IQR-based feature scaling (e.g., robust scaling) is gaining traction to handle outliers in high-dimensional datasets. Meanwhile, big data analytics tools are integrating automated IQR calculations with visualization dashboards, reducing manual errors in exploratory analysis.Emerging trends include:
The future of the IQR lies in its adaptability—whether in quantitative finance, AI-driven analytics, or regulatory compliance, its ability to distill complexity into actionable insights remains unmatched.

Conclusion
The interquartile range is more than a statistical curiosity; it’s a practical tool for professionals who demand accuracy in the face of messy data. Knowing how to find the interquartile range—whether through linear interpolation, Tukey’s hinges, or software defaults—empowers analysts to make informed decisions, from identifying outliers in clinical trials to assessing market risk. The key is not just memorizing the formula but understanding the context: dataset size, industry standards, and the method’s limitations.As data grows more complex, the IQR’s role as a robust measure of spread will only strengthen. By mastering its calculation and application, you’re not just solving a statistical problem—you’re equipping yourself with a skill that transcends disciplines.
Comprehensive FAQs
Q: Why does the IQR matter more than the standard deviation in skewed data?
The standard deviation is highly sensitive to outliers and assumes a normal distribution. The IQR focuses on the central 50% of data, making it far more reliable for skewed distributions (e.g., income data, reaction times). For example, in a right-skewed dataset, the mean and standard deviation may overstate variability, while the IQR remains stable.
Q: How do I calculate the IQR in Excel without errors?
Use the QUARTILE.INC function for Q1 and Q3, then subtract:
=QUARTILE.INC(range, 1) - QUARTILE.INC(range, 3).
Excel’s default method is linear interpolation, but ensure your data is sorted to avoid miscalculations. For older versions, use =PERCENTILE.INC(range, 0.25) and =PERCENTILE.INC(range, 0.75).
Q: Can the IQR be negative?
No. Since Q3 is always ≥ Q1 in sorted data, the IQR (Q3 – Q1) is always non-negative. A negative result would indicate unsorted data or a calculation error.
Q: What’s the difference between IQR and range?
The range (max – min) measures total spread and is highly sensitive to outliers. The IQR measures the spread of the middle 50%, ignoring extremes. For example, in [1, 2, 3, 100], the range is 99, but the IQR is 2 (Q1=2, Q3=3), reflecting the true central variability.
Q: How does the IQR relate to boxplots?
The IQR defines the height of the box in a boxplot. The "whiskers" extend to 1.5×IQR beyond Q1/Q3, and data points beyond this are plotted as outliers. This visualization directly communicates the IQR’s role in summarizing data distribution.
Q: Which quartile method should I use for small datasets (n < 20)?
For small n, Tukey’s hinges or linear interpolation are preferred. Tukey’s method avoids interpolation artifacts, while linear interpolation provides smoother estimates. Avoid the nearest-rank method, as it can produce erratic results with limited data points.
Q: Can the IQR be used for categorical data?
No. The IQR requires ordered, numerical data. For categorical variables, use measures like mode or frequency distributions instead.
Q: How does the IQR help in outlier detection?
Outliers are typically defined as values below Q1 – 1.5×IQR or above Q3 + 1.5×IQR. This rule (based on Tukey’s method) identifies extreme values while accounting for the data’s natural spread, unlike arbitrary thresholds.
Q: Is the IQR affected by sample size?
Yes. With small n, the IQR may be less stable due to the limited number of data points influencing Q1/Q3. For n < 10, consider using alternative methods like the median absolute deviation (MAD) for robustness.
Q: Why do different software tools (Excel, R, Python) give different IQR results?
Each tool uses a default quartile method:
QUARTILE.INC).quantile().numpy.percentile).type=2 in R for linear interpolation).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.