What Is Correlation? The Hidden Patterns Shaping Data and Decisions
The numbers don’t lie—but they rarely speak alone. A stock price climbs alongside consumer confidence; ice cream sales surge when temperatures rise; crime rates drop as education levels climb. These aren’t coincidences. They’re correlations, the silent language of data that reveals how variables move in tandem, whether through cause, chance, or some unseen thread. What is correlation, then, is the art of detecting these relationships without presuming their meaning—a discipline that separates insight from illusion in fields as diverse as medicine, economics, and machine learning.
The danger lies in mistaking correlation for causation. A study might show that children who eat more candy sleep worse, but does sugar disrupt sleep, or do hyperactive kids simply consume more candy and resist bedtime? The distinction isn’t just academic; it’s the difference between a breakthrough and a misstep. Governments have launched policies based on flawed correlations, investors have bet fortunes on spurious trends, and scientists have chased red herrings for decades—all because the question of what is correlation was answered too hastily.
Yet correlation remains the bedrock of modern analysis. It’s the first tool researchers wield when faced with complexity, the lens through which economists peer into markets, and the compass that guides data scientists through vast datasets. To ignore it is to risk blindness; to wield it recklessly is to invite error. The key, as statisticians and philosophers of science have long argued, is to treat correlation as a hypothesis generator—not a verdict.
The Complete Overview of What Is Correlation
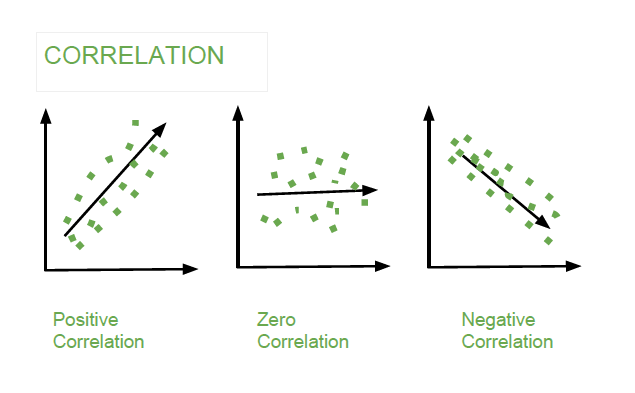
Correlation measures the degree to which two variables change together, quantified as a value between -1 and 1. A perfect positive correlation (1) means one variable rises or falls in lockstep with another; a perfect negative correlation (-1) means one moves inversely. At zero, no relationship exists. But the number alone tells only part of the story. Context matters: a 0.9 correlation between two variables might be meaningful in physics but trivial in social sciences, where human behavior introduces noise. What is correlation, fundamentally, is a statistical handshake between variables—a way to ask, “Do these things tend to move together, and if so, how strongly?”The misconception that correlation implies causation persists because the human brain craves narratives. We see patterns where none exist (the “clustering illusion”) and assume connections where only coincidence reigns. Yet correlation’s true power lies in its agnosticism. It doesn’t claim to explain why; it simply flags what. This makes it indispensable in exploratory analysis, where researchers fish for potential causes before designing experiments. A pharmaceutical company might spot a correlation between a drug’s dosage and patient recovery rates—a clue worth pursuing, even if the mechanism remains unknown.
Historical Background and Evolution
The concept of what is correlation emerged from the 19th century’s statistical revolution, when mathematicians sought to quantify the chaos of the natural and social worlds. Francis Galton, Charles Darwin’s cousin, pioneered correlation analysis in the 1880s while studying inheritance patterns in peas. His work laid the groundwork for regression analysis, a tool that would later become the backbone of predictive modeling. Galton’s “coefficient of correlation” was one of the first attempts to measure how traits—like height or intelligence—clustered across generations, challenging deterministic views of heredity.By the early 20th century, statisticians like Karl Pearson formalized correlation into a mathematical framework, introducing the Pearson correlation coefficient (r). This innovation transformed fields like biology, where researchers could now test hypotheses about evolution, and economics, where policymakers studied the links between unemployment and inflation. The rise of computers in the late 20th century democratized correlation analysis, allowing scientists to crunch vast datasets and uncover relationships that would have been impossible to detect manually. Today, algorithms automatically compute correlations in real time, from stock market fluctuations to climate data—but the core principle remains unchanged: what is correlation is the study of how variables dance together, whether in nature or human systems.
Core Mechanisms: How It Works
At its core, correlation is a measure of linear association. Given two variables, X and Y, the Pearson correlation coefficient calculates how well a straight line can describe their relationship. For example, if X increases by 1 unit and Y increases by 0.8 units consistently, the correlation will be high. The formula accounts for deviations from the mean, penalizing pairs of data points that stray far from the implied trend. This is why outliers can distort correlation: a single extreme value can skew the coefficient, masking the true relationship for the rest of the data.Table of Contents
- The Complete Overview of What Is Correlation
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can correlation be negative?
- Q: How do I know if a correlation is statistically significant?
- Q: What’s the difference between correlation and covariance?
- Q: Why do outliers affect correlation?
- Q: Can correlation be used to predict the future?
- Q: How do I interpret a correlation coefficient of 0.3?
- Q: What’s the “spurious correlation” problem?
Beyond Pearson’s linear correlation, other methods exist for non-linear relationships. Spearman’s rank correlation, for instance, assesses how two variables’ rankings align, useful when data is ordinal (e.g., survey responses). Partial correlation isolates the relationship between two variables while controlling for a third, revealing whether the link persists when other factors are accounted for. These techniques underscore a critical truth: what is correlation is not a monolithic concept but a toolkit, adaptable to the data’s nature. Whether linear or non-linear, the goal is the same—to quantify the extent to which variables move in harmony or opposition.
Key Benefits and Crucial Impact
Correlation is the bridge between raw data and actionable insight. In medicine, it helps identify risk factors for diseases; in finance, it predicts market movements; in marketing, it refines customer segmentation. The ability to spot patterns where others see noise has made correlation a cornerstone of evidence-based decision-making. Yet its value extends beyond practical applications. By revealing hidden connections, correlation challenges assumptions, forces rigor, and often sparks new questions. A high correlation between two variables might not explain why they’re linked, but it does demand an explanation—a scientific imperative that drives progress.The flip side is correlation’s potential to mislead. The late statistician David Freedman warned that “correlation is not causation,” a mantra repeated in textbooks and courtrooms alike. The danger isn’t just in false conclusions but in the resources wasted chasing phantom causes. A famous example: In the 1950s, researchers found a strong correlation between ice cream sales and drowning deaths—both rising in summer. The “causal” explanation? Ice cream causes drowning. The reality? Heat causes both. Such errors highlight why what is correlation must be paired with domain knowledge and experimental design to avoid embarrassing—or costly—mistakes.
“Correlation does not imply causation, but it does waggle its eyebrows suggestively and gesture furtively while mouthing, ‘Look over there.’” —Nassim Nicholas Taleb, Antifragile
Major Advantages
- Pattern Detection: Correlation scans vast datasets to identify relationships that would be invisible to human analysis, such as the link between microeconomic indicators and macroeconomic trends.
- Hypothesis Generation: It serves as a starting point for further research, directing scientists toward variables worth studying in controlled experiments.
- Risk Assessment: Financial models use correlation matrices to diversify portfolios, mitigating risk by balancing assets that don’t move in tandem.
- Predictive Power: In machine learning, correlated features improve model accuracy by capturing underlying structures in data.
- Interdisciplinary Utility: From epidemiology (tracking disease spread) to urban planning (analyzing traffic patterns), correlation is a universal language for quantifying relationships.

Comparative Analysis
| Correlation | Causation |
|---|---|
| Describes the strength/direction of a relationship between variables. | Establishes that one variable directly influences another. |
| Measured via coefficients (e.g., Pearson’s r, Spearman’s ρ). | Proven through controlled experiments or longitudinal studies. |
| Can be spurious (e.g., storks delivering babies). | Requires evidence of mechanism or intervention. |
| Useful for exploratory data analysis. | Essential for policy, medicine, and engineering. |
Future Trends and Innovations
As data grows more complex, correlation analysis is evolving beyond simple pairwise relationships. Multivariate correlations—examining how multiple variables interact simultaneously—are becoming standard in fields like genomics and climate science. Machine learning models now compute “feature importance” correlations, ranking variables by their predictive power in high-dimensional spaces. Meanwhile, causal inference techniques, such as Granger causality and structural causal models, are bridging the gap between correlation and causation, allowing researchers to infer directionality from observational data.The rise of big data and real-time analytics will further democratize correlation analysis, making it accessible to industries beyond academia. However, the challenge will be managing “correlation overload”—the risk of drowning in false positives as algorithms flag thousands of weak relationships. Future advancements may focus on contextualizing correlations, integrating them with domain expertise, and developing tools to distinguish meaningful patterns from noise. What is correlation in the coming decades may less about numbers and more about narrative—telling the story behind the statistics.

Conclusion
Correlation is neither a magic bullet nor a red herring; it’s a lens, a question mark, and a compass. Its strength lies in its simplicity: two variables, a number, and an invitation to dig deeper. Yet its weakness is its ambiguity—every correlation is a story waiting to be told, but not all stories are true. The lesson for researchers, policymakers, and data enthusiasts alike is to treat correlation as a conversation starter, not a conclusion. Ask why. Test rigorously. And remember: in the dance of data, correlation is the first step, but causation is the waltz.The next time you see two variables moving in sync, pause before assuming you know the reason. What is correlation is the art of seeing connections—but wisdom lies in knowing when to stop looking.
Comprehensive FAQs
Q: Can correlation be negative?
A: Yes. A negative correlation (e.g., -0.8) means one variable increases as the other decreases. For example, temperature and heating bills are negatively correlated: as temperatures rise, heating costs fall.
Q: How do I know if a correlation is statistically significant?
A: Significance depends on the correlation coefficient’s magnitude and the sample size. A p-value (typically < 0.05) tests whether the observed correlation is unlikely to have occurred by chance. Tools like t-tests for Pearson’s r can help determine this.
Q: What’s the difference between correlation and covariance?
A: Covariance measures how two variables change together, but without standardization—its scale depends on the variables’ units. Correlation standardizes covariance to a -1 to 1 range, making it unitless and comparable across datasets.
Q: Why do outliers affect correlation?
A: Correlation is sensitive to extreme values because it’s based on deviations from the mean. A single outlier can skew the line of best fit, inflating or deflating the correlation coefficient. Robust methods (e.g., Spearman’s rank) can mitigate this.
Q: Can correlation be used to predict the future?
A: Correlation alone cannot predict future events, but it can inform predictive models. For example, historical correlations between GDP growth and unemployment might help forecast job markets—though other factors (e.g., policy changes) must also be considered.
Q: How do I interpret a correlation coefficient of 0.3?
A: A coefficient of 0.3 indicates a weak positive correlation. While not strong enough to imply causation, it suggests a tendency for the variables to move in the same direction. Context matters: in psychology, 0.3 might be meaningful; in physics, it may be negligible.
Q: What’s the “spurious correlation” problem?
A: Spurious correlations occur when two variables appear related but are linked by a third, unseen factor (e.g., divorce rates and whiskey consumption both rise with temperature). Always seek underlying mechanisms or test for confounding variables.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.