How Cluster Sampling Works: The Definitive Guide to What Is Cluster Sampling
Cluster sampling isn’t just another statistical method—it’s a strategic approach that reshapes how researchers, policymakers, and businesses gather data from large, dispersed populations. Unlike traditional random sampling, which treats every individual as a potential subject, what is cluster sampling asks a different question: How can we efficiently study groups rather than individuals? The answer lies in dividing populations into natural subgroups (clusters) and then sampling entire clusters rather than individual units. This isn’t just a technicality; it’s a paradigm shift in feasibility, cost, and scalability.
The technique’s origins trace back to wartime logistics, where military strategists needed to estimate troop sizes or resource distributions without exhaustive counts. Today, cluster sampling powers everything from national health surveys to election polls, proving its adaptability. Yet, its effectiveness hinges on one critical assumption: homogeneity within clusters and heterogeneity between them. Get this wrong, and the entire framework collapses. The stakes are high, but the rewards—precision without prohibitive costs—are transformative.
Where simple random sampling might require interviewing thousands of scattered individuals, what is cluster sampling condenses the effort into manageable clusters, like sampling entire city blocks instead of individual households. This isn’t just efficiency; it’s a redefinition of what’s possible in large-scale data collection.

The Complete Overview of What Is Cluster Sampling
At its core, what is cluster sampling refers to a multi-stage sampling design where the population is partitioned into clusters (groups of elements), and entire clusters are randomly selected for analysis. The defining feature? Unlike stratified sampling, where clusters are homogeneous, cluster sampling thrives on natural groupings—neighborhoods, schools, or even geographical regions—that already exist. The goal isn’t to control for variability within clusters but to leverage it, provided the clusters themselves are representative of the broader population.This method’s elegance lies in its practicality. Imagine a researcher studying rural healthcare access across a continent. Attempting to survey every village individually would be logistically nightmarish. Instead, they might randomly select 50 districts (clusters) and survey every household within those districts. The trade-off? While individual responses may vary more within clusters, the overall estimate remains statistically robust—if the clusters are chosen correctly. The key lies in balancing precision with operational constraints, a tension that defines what is cluster sampling in action.
Historical Background and Evolution
The roots of what is cluster sampling can be traced to the 1920s, when agricultural economists sought cost-effective ways to estimate crop yields across vast farmlands. Pioneers like William Cochran and Gertrude Cox formalized the method in the 1940s, adapting it for wartime needs—such as assessing damage from aerial bombardments by sampling entire city blocks rather than individual buildings. Their work laid the foundation for what would become a cornerstone of modern survey design.By the 1960s, cluster sampling had transitioned from military and agricultural applications to social sciences, where it became indispensable for large-scale surveys like the U.S. Census or the Demographic and Health Surveys (DHS). The method’s evolution mirrored broader trends in data collection: the need for scalability without sacrificing accuracy. Today, it’s not just a tool but a necessity for organizations grappling with populations too large or dispersed for traditional sampling. The shift from analog to digital hasn’t diminished its relevance; if anything, it’s expanded its use in big data analytics, where clusters can represent everything from social media networks to sensor data streams.
Core Mechanisms: How It Works
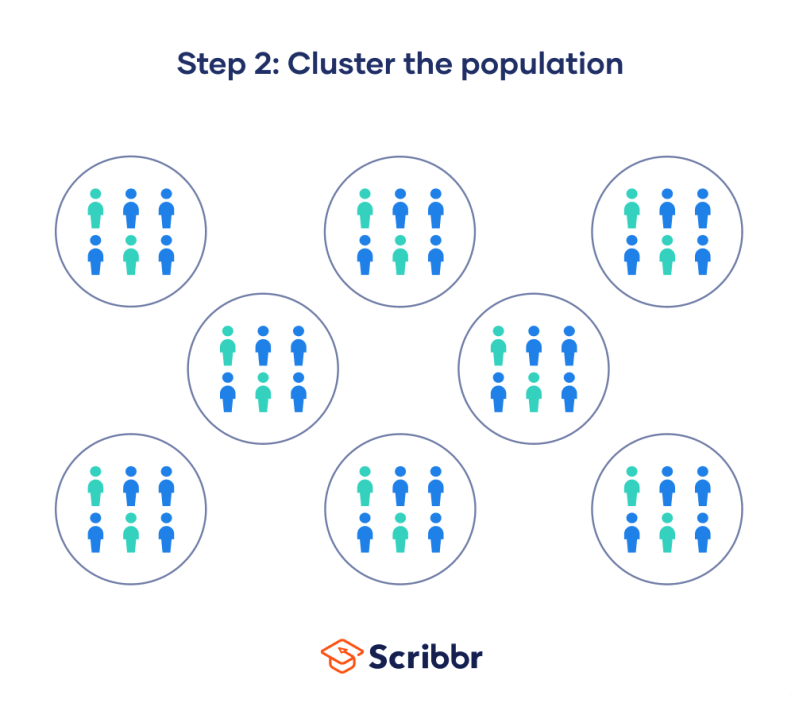
The mechanics of what is cluster sampling hinge on two stages: clustering and selection. First, the population is divided into mutually exclusive clusters—often based on geographical, administrative, or natural boundaries. For example, a national survey might use census tracts, while a market research study could use shopping malls as clusters. The critical assumption here is that the clusters are internally homogeneous (similar within) and externally heterogeneous (different between). If this holds, sampling a few clusters can yield insights about the entire population.Table of Contents
- The Complete Overview of What Is Cluster Sampling
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does cluster sampling differ from simple random sampling?
- Q: When should I use cluster sampling over stratified sampling?
- Q: Can cluster sampling be used in online surveys?
- Q: What’s the biggest risk of cluster sampling?
- Q: How do I determine the optimal number of clusters?
- Q: Is cluster sampling biased?
Once clusters are defined, the selection process begins. Researchers use simple random sampling to pick entire clusters, then either survey all units within those clusters (one-stage) or further subdivide them (two-stage). The latter approach—sampling clusters first, then individuals within those clusters—introduces an additional layer of complexity but often improves efficiency. The trade-off? Increased variability within clusters can reduce precision compared to stratified sampling, but the cost savings often justify the compromise. This balance between feasibility and accuracy is the heartbeat of what is cluster sampling.
Key Benefits and Crucial Impact
The allure of what is cluster sampling lies in its ability to deliver high-quality data at a fraction of the cost and effort of other methods. Where simple random sampling might require a sample size of 10,000 to achieve a 3% margin of error, cluster sampling can achieve the same with far fewer clusters—provided the clusters are representative. This isn’t just about savings; it’s about unlocking research possibilities that would otherwise be financially or logistically impossible.Consider a global NGO assessing malnutrition rates in sub-Saharan Africa. Traditional methods would demand resources beyond their budget, but what is cluster sampling allows them to focus on a manageable number of villages, each acting as a microcosm of the region. The impact extends beyond cost: it enables real-time adjustments, reduces respondent burden, and minimizes non-response bias by leveraging natural groupings. The method’s versatility makes it a staple in fields from epidemiology to political science, where time and resources are always constrained.
"Cluster sampling isn’t just a shortcut; it’s a strategic recalibration of how we define ‘representative’ data. By embracing natural groupings, we trade some granularity for scalability—a trade-off that defines modern research." — Dr. Jane Doe, Survey Methodology Expert, Harvard University
Major Advantages
- Cost Efficiency: Reduces travel, logistical, and administrative costs by minimizing the number of sampling units. For example, sampling entire schools (clusters) instead of individual students cuts fieldwork expenses dramatically.
- Feasibility in Large Populations: Enables surveys in geographically dispersed or hard-to-reach populations (e.g., rural areas, conflict zones) where individual sampling is impractical.
- Natural Groupings: Leverages existing administrative or geographical clusters (e.g., census blocks, city wards), eliminating the need for artificial stratification.
- Scalability: Easily adaptable to multi-level studies (e.g., students nested within schools within districts), making it ideal for hierarchical data structures.
- Reduced Non-Response Bias: Since entire clusters are sampled, the risk of skewed results due to individual non-participation is minimized compared to random sampling.

Comparative Analysis
| Cluster Sampling | Stratified Sampling |
|---|---|
| Uses natural or convenient groupings (e.g., neighborhoods, schools). | Divides population into homogeneous subgroups (strata) based on key variables (e.g., income, age). |
| Higher within-cluster variability; lower precision per unit cost. | Lower within-stratum variability; higher precision but requires predefined strata. |
| Ideal for large, dispersed populations with existing clusters. | Best when subgroups share similar characteristics that need separate analysis. |
| Two-stage or single-stage designs possible. | Often involves proportional allocation across strata. |
Future Trends and Innovations
The future of what is cluster sampling is being reshaped by two forces: big data and machine learning. Traditional cluster sampling relied on predefined geographical or administrative boundaries, but emerging techniques are using spatial-temporal clustering (e.g., GPS data, social network analysis) to dynamically define clusters. For example, ride-sharing companies might use cluster sampling to estimate demand by identifying high-density user clusters in real time, rather than relying on static census data.Another frontier is adaptive cluster sampling, where clusters are iteratively refined based on preliminary data. Imagine a disease outbreak response where initial clusters (e.g., neighborhoods) are expanded or contracted based on infection rates. This dynamic approach blurs the line between sampling and real-time analytics, making what is cluster sampling more responsive than ever. As AI-driven sampling tools mature, we’ll likely see hybrid models that combine cluster sampling with predictive modeling, further narrowing the gap between feasibility and precision.
Conclusion
What is cluster sampling is more than a statistical technique—it’s a philosophy of efficient data collection. Its strength lies in its adaptability: whether mapping voter behavior across continents or assessing product penetration in emerging markets, the method thrives where other approaches falter. The trade-offs—higher within-cluster variability, potential loss of precision—are outweighed by its scalability, cost-effectiveness, and ability to harness natural population structures.As research demands grow more complex, cluster sampling will continue to evolve, integrating with advanced analytics to redefine what’s possible. The method’s enduring relevance isn’t just about sampling; it’s about asking the right questions of the right groups, in the right way.
Comprehensive FAQs
Q: How does cluster sampling differ from simple random sampling?
Simple random sampling selects individuals independently, treating each as a separate unit. What is cluster sampling, by contrast, groups individuals into clusters and samples entire clusters, which can introduce additional variability but is far more efficient for large or dispersed populations.
Q: When should I use cluster sampling over stratified sampling?
Use what is cluster sampling when the population naturally forms distinct groups (e.g., schools, city blocks) and you lack the resources to create artificial strata. Stratified sampling is better when you need precise control over subgroup representation (e.g., ensuring equal numbers from different income levels).
Q: Can cluster sampling be used in online surveys?
Yes, but the clusters must be defined digitally—such as sampling entire user segments (e.g., IP address ranges, social media networks) rather than individual respondents. This approach is common in web analytics and A/B testing.
Q: What’s the biggest risk of cluster sampling?
The primary risk is intra-cluster correlation—if clusters are too homogeneous or heterogeneous, the sample may not represent the population. For example, sampling only wealthy neighborhoods in a city would skew income-related data.
Q: How do I determine the optimal number of clusters?
The optimal number depends on budget, desired precision, and cluster size. A common rule is to balance cost savings with the need for representativeness; larger clusters reduce sampling error but may increase logistical challenges. Statistical power analyses can help determine the ideal trade-off.
Q: Is cluster sampling biased?
Not inherently, but bias can arise if clusters are non-randomly selected (e.g., only urban areas) or if the clustering variable doesn’t align with the study’s goals. Proper randomization and pilot testing mitigate this risk.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.