How Systematic Sampling Works: The Definitive Guide to What Is Systematic Sampling
When researchers or analysts face a dataset too vast to examine in full, they turn to sampling techniques. Among these, what is systematic sampling emerges as a structured, efficient method—one that balances simplicity with statistical rigor. Unlike random selection, which relies on pure chance, systematic sampling introduces a deliberate interval, ensuring coverage while reducing bias. This approach isn’t just theoretical; it’s deployed in everything from market research to epidemiological studies, where precision matters.
Yet its elegance lies in its deceptive simplicity. A well-designed systematic sample can mirror the complexity of a population with minimal effort, provided the underlying structure isn’t periodic (a critical caveat often overlooked). The method’s efficiency makes it a staple in fields where time and resources are constrained, but its effectiveness hinges on understanding its nuances—something many practitioners underestimate.
The rise of big data hasn’t diminished its relevance. In an era where datasets grow exponentially, systematic sampling remains a cornerstone of scalable analysis. Whether applied to customer feedback surveys or environmental monitoring, its ability to deliver reliable insights without exhaustive collection sets it apart from other techniques.

The Complete Overview of Systematic Sampling
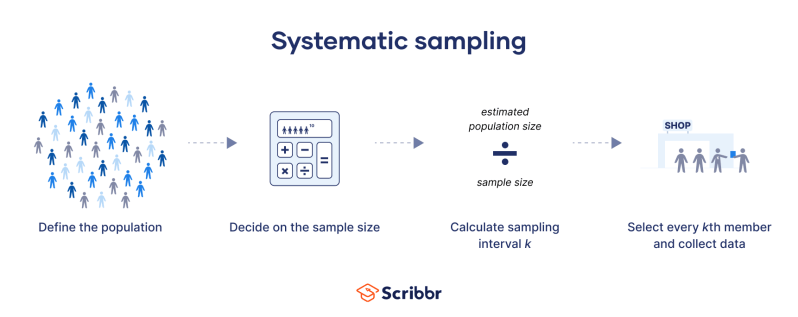
Systematic sampling is a probabilistic method where elements are selected from an ordered sampling frame at regular intervals. The process begins with defining a population size (N) and a desired sample size (n), from which a sampling interval (k) is calculated as k = N/n. Starting at a randomly chosen point between 1 and k, every k-th element is then included in the sample. This interval-based selection ensures even distribution across the population, provided no hidden patterns exist in the ordering.What distinguishes systematic sampling from other methods is its combination of simplicity and control. Unlike stratified sampling, which divides populations into homogeneous subgroups, or cluster sampling, which groups elements geographically, systematic sampling treats the entire population as a single continuous frame. This makes it particularly useful for large, homogeneous populations where stratification isn’t necessary. However, its strength—predictability—can become a weakness if the population’s underlying order introduces bias, a risk that demands careful frame design.
Historical Background and Evolution
The origins of systematic sampling trace back to the early 20th century, when statisticians sought efficient ways to analyze large datasets without sacrificing representativeness. Pioneers like Jerzy Neyman and Eugene L. Scott formalized sampling theory in the 1930s, laying the groundwork for systematic methods. Their work addressed a critical need: how to reduce survey costs while maintaining accuracy, especially in agricultural and census studies where manual data collection was labor-intensive.By the mid-20th century, systematic sampling gained traction in social sciences and market research, thanks to its computational efficiency. The advent of digital databases in the late 20th century further cemented its role, as electronic sampling frames eliminated the need for physical sorting. Today, what is systematic sampling is taught alongside other probabilistic techniques, but its evolution reflects a broader shift toward automation—where human oversight ensures the method’s integrity despite algorithmic execution.
Core Mechanisms: How It Works
At its core, systematic sampling operates on three pillars: a defined population, a random start, and a fixed interval. The population must be ordered (e.g., alphabetically, by ID, or chronologically), and the sampling interval k is derived by dividing the population size by the desired sample size. For example, in a population of 1,000 with a sample size of 100, k would be 10, meaning every 10th element is selected after a random start between 1 and 10.Table of Contents
- The Complete Overview of Systematic Sampling
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What is systematic sampling, and how does it differ from random sampling?
- Q: When should I use systematic sampling instead of stratified or cluster sampling?
- Q: How do I avoid periodic bias in systematic sampling?
- Q: Can systematic sampling be used for qualitative research?
- Q: What software tools support systematic sampling?
The random start is critical—it prevents periodic biases that could arise if the interval aligned with an unobserved pattern (e.g., weekly cycles in sales data). Once the start is chosen, the sample is built by adding k repeatedly until the desired n is reached. This linear progression ensures uniformity, but it also assumes the population’s order is random or irrelevant, a assumption that must be validated before implementation.
Key Benefits and Crucial Impact
Systematic sampling’s appeal lies in its ability to deliver balanced samples with minimal resource expenditure. Unlike simple random sampling, which requires generating and tracking individual random numbers, systematic sampling automates selection through interval logic. This efficiency is particularly valuable in large-scale studies where manual processes would be impractical. Additionally, its structured approach reduces sampling error compared to convenience or judgmental methods, where bias is more likely to creep in.The method’s impact extends beyond academia. Industries from healthcare to retail rely on systematic sampling to monitor trends, test products, or audit records. Its scalability makes it ideal for real-time data collection, where delays could compromise results. Yet, its effectiveness hinges on one non-negotiable condition: the absence of periodic trends in the sampling frame. Ignore this, and the sample may become a distorted reflection of the population.
"Systematic sampling is not a panacea, but when applied correctly, it offers a cost-effective bridge between simplicity and statistical validity." — Dr. Harold Cochran, Sampling Theory Expert
Major Advantages
- Efficiency: Reduces time and labor by automating selection via fixed intervals, ideal for large populations.
- Representativeness: Ensures even coverage if the population is randomly ordered, minimizing selection bias.
- Simplicity: Easier to implement than stratified or cluster sampling, requiring only basic arithmetic.
- Scalability: Adapts to datasets of any size without proportional increases in complexity.
- Predictability: Produces consistent results when applied to stable populations, aiding reproducibility.
Comparative Analysis
| Systematic Sampling | Simple Random Sampling |
|---|---|
| Selects every k-th element after a random start. | Each element has an equal, independent chance of selection. |
| Risk of bias if population has hidden periodicity. | No inherent bias, but requires complex randomization for large N. |
| Lower sampling error for ordered populations. | Higher sampling error if population is heterogeneous. |
| Best for homogeneous, ordered datasets. | Best for small populations or when complete randomness is critical. |
Future Trends and Innovations
As data volumes expand, systematic sampling is evolving to integrate with machine learning and adaptive frameworks. Emerging techniques, such as adaptive systematic sampling, adjust intervals dynamically based on real-time data patterns, reducing the risk of periodic bias. Meanwhile, blockchain-based sampling frames could further enhance transparency, ensuring intervals are tamper-proof. The future may also see hybrid models, combining systematic selection with stratified or cluster methods to optimize for both efficiency and precision.The rise of automated tools—like R’s `survey` package or Python’s `statsmodels`—has democratized systematic sampling, but its theoretical foundations remain unchanged. The challenge ahead lies in balancing automation with human oversight, particularly as AI-driven sampling tools proliferate. Without rigorous validation, even systematic methods could succumb to algorithmic biases, underscoring the need for ongoing methodological refinement.

Conclusion
Systematic sampling endures because it solves a fundamental problem: how to extract meaningful insights from vast, ordered datasets without exhaustive effort. Its strength is its structure—predictable, repeatable, and scalable—but this same structure demands vigilance. Researchers must validate sampling frames, test for periodicity, and recognize when other methods (e.g., stratified sampling) might better suit heterogeneous populations. When applied correctly, what is systematic sampling remains one of the most practical tools in the statistician’s arsenal.In an age where data is abundant but attention is scarce, systematic sampling offers a middle path: efficient enough to keep projects moving, yet rigorous enough to ensure validity. Its future will likely hinge on adaptability—embracing new technologies while preserving the core principles that have made it indispensable for over a century.
Comprehensive FAQs
Q: What is systematic sampling, and how does it differ from random sampling?
Systematic sampling selects elements at fixed intervals from an ordered population, starting at a random point. Unlike simple random sampling—where every element has an independent chance of selection—it relies on a structured interval (k = N/n), which can introduce bias if the population has hidden patterns. Random sampling avoids this but is less efficient for large datasets.
Q: When should I use systematic sampling instead of stratified or cluster sampling?
Use systematic sampling when your population is homogeneous and ordered (e.g., customer IDs, time-series data), and you need a balance of simplicity and representativeness. Stratified sampling is better for heterogeneous populations, while cluster sampling suits geographically grouped data. Systematic methods excel in cost-sensitive scenarios where stratification isn’t necessary.
Q: How do I avoid periodic bias in systematic sampling?
Periodic bias occurs if the sampling interval (k) aligns with an unobserved cycle in the population (e.g., weekly sales peaks). To mitigate this, shuffle the sampling frame randomly before applying the interval, or use a random start within the first k elements. Always test for autocorrelation in the data if periodicity is suspected.
Q: Can systematic sampling be used for qualitative research?
While systematic sampling is primarily quantitative, it can inform qualitative sampling strategies (e.g., selecting every n-th interview transcript for thematic analysis). However, qualitative research often relies on purposive or snowball sampling, where systematic methods may not capture the depth of non-probabilistic selection.
Q: What software tools support systematic sampling?
Popular tools include R (`survey` package), Python (`statsmodels`, `pandas`), and SPSS (via custom scripts). For large-scale applications, SAS and Stata also offer systematic sampling functions. Open-source alternatives like JASP provide accessible options for researchers without proprietary software access.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.