How Python’s set Transforms Data Handling—Beyond Basic Lists
Python’s set is one of its most underrated yet powerful tools—a data structure that redefines how developers manage uniqueness, speed, and logic. Unlike lists or dictionaries, a set python implementation prioritizes hash-based storage, ensuring O(1) average-time complexity for membership tests. This alone makes it indispensable for tasks ranging from deduplication to mathematical set operations. Yet, its true potential lies in its ability to simplify complex workflows, from filtering datasets to optimizing algorithms.
The elegance of set python lies in its simplicity. A single line—`my_set = {1, 2, 3}`—can replace hours of manual iteration to remove duplicates. But beneath this surface-level convenience is a sophisticated system designed for efficiency. Python’s set isn’t just a collection; it’s a high-performance abstraction that leverages hashing to guarantee fast lookups, modifications, and comparisons. This makes it a cornerstone for developers working with large-scale data or performance-critical applications.
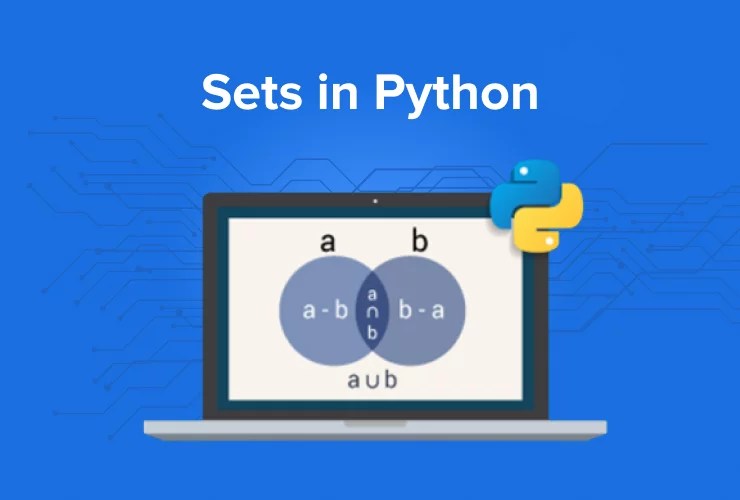
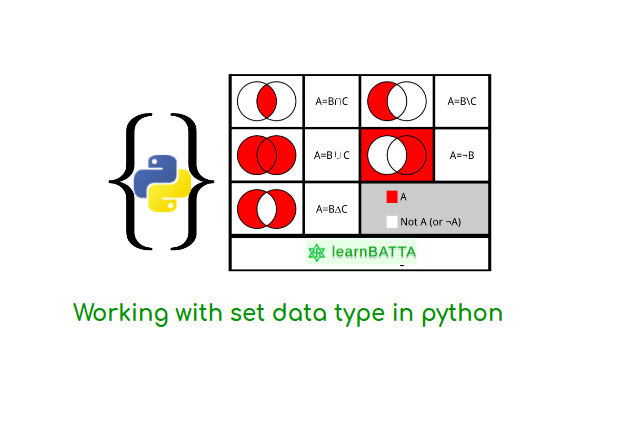
What distinguishes set python from other structures is its adherence to mathematical set theory. Operations like union, intersection, and difference aren’t just syntactic sugar—they’re optimized at the language level. This means developers can write concise code that executes with near-native speed, a critical advantage in fields like data science, cybersecurity, and systems programming.
The Complete Overview of Python’s Set Data Structure
Python’s set is a mutable, unordered collection of unique elements, designed to enforce one core principle: no duplicates. This design choice stems from its roots in mathematical set theory, where sets inherently represent distinct, unordered groups. In Python, this translates to a data structure that combines the speed of hash tables with the logical rigor of set operations. Unlike lists, which allow duplicates and maintain insertion order, a set python ensures every element is distinct and accessed via hashing, making it ideal for scenarios where uniqueness is non-negotiable.The implementation of set python in CPython (Python’s standard interpreter) relies on a dynamic array of hash buckets, where each element’s hash value determines its storage location. This structure enables average-case O(1) time complexity for add, remove, and membership operations—a stark contrast to lists, which degrade to O(n) for these tasks. The trade-off? Sets are unordered and lack indexing, but this limitation is often outweighed by their performance benefits. For developers, this means set python isn’t just a tool for deduplication; it’s a paradigm shift in how data is processed.
Historical Background and Evolution
The concept of sets predates Python itself, tracing back to Georg Cantor’s 19th-century work on set theory. However, Python’s set structure was introduced in version 2.3 (released in 2003) as part of PEP 218, which formalized the `set` and `frozenset` types. Before this, developers relied on workarounds like dictionaries (with keys) or manual loops to simulate set behavior. The addition of set python was a direct response to the growing need for efficient, built-in support for mathematical set operations in data-intensive applications.The evolution of set python didn’t stop at basic functionality. Python 2.6 and later versions optimized the underlying hash table implementation, reducing collisions and improving memory efficiency. By Python 3, the language standardized set as a primary collection type, deprecating the older `sets` module in favor of the built-in `set()`. This transition reflected a broader trend: Python’s commitment to performance and usability, where set python became a first-class citizen for developers demanding both speed and clarity.
Core Mechanisms: How It Works
At its core, a set python is a hash-based structure. When you create a set—`unique_items = {1, 2, 3}`—Python computes a hash for each element and stores it in a table. This hash determines the element’s position, allowing O(1) average-time lookups. The magic happens during operations: adding an element checks its hash first; if it already exists, the operation is ignored. This mechanism ensures uniqueness without manual checks, a process that would be O(n) in a list.Table of Contents
- The Complete Overview of Python’s Set Data Structure
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can a set python contain mutable elements like lists or dictionaries?
- Q: How does set python handle collisions in its hash table?
- Q: What’s the difference between `set` and `frozenset` in Python?
- Q: Are there performance trade-offs when using set python for large datasets?
- Q: Can I convert a list to a set python to remove duplicates?
- Q: How does set python compare to NumPy’s `setdiff1d` for numerical data?
The unordered nature of set python is a deliberate design choice. Since elements are accessed via hashing rather than indices, their sequence isn’t preserved. However, this trade-off enables optimizations like fast union and intersection operations. For example, `set_a.union(set_b)` doesn’t iterate through each element sequentially—instead, it leverages hash tables to merge sets in linear time relative to their combined size. This efficiency is why set python is the go-to for tasks like merging datasets or finding common elements between collections.
Key Benefits and Crucial Impact
The adoption of set python in modern development isn’t accidental. It’s a response to the demands of scalability and precision. In an era where datasets grow exponentially, the ability to deduplicate or compare collections in milliseconds can mean the difference between a functional script and a high-performance system. Set python delivers this by abstracting away the complexity of manual iteration, allowing developers to focus on logic rather than implementation details.Beyond raw speed, set python introduces a declarative approach to data manipulation. Operations like intersection (`&`) or symmetric difference (`^`) read like mathematical expressions, making code more intuitive. This aligns with Python’s philosophy of readability, where complex operations are expressed concisely. For teams working on collaborative projects, set python reduces cognitive overhead, as its syntax mirrors its purpose.
"Sets are to lists as mathematics is to arithmetic: they elevate operations from tedious to transformative." — Guido van Rossum (Python’s creator, in a 2004 interview on Python’s evolution)
Major Advantages
- O(1) Membership Testing: Checking if an element exists in a set python is instantaneous, whereas lists require O(n) scans.
- Automatic Deduplication: Adding elements to a set automatically discards duplicates, eliminating the need for manual filtering.
- Optimized Set Operations: Operations like union, intersection, and difference execute in near-linear time due to hash-based indexing.
- Memory Efficiency: Sets store only unique elements, reducing memory usage compared to lists with duplicates.
- Integration with Math Logic: The syntax for set operations (`|`, `&`, `-`) mirrors mathematical notation, improving code clarity.
Comparative Analysis
| Feature | Python Set vs. List |
|---|---|
| Order | Unordered (no indexing) vs. Ordered (index-based access) |
| Duplicates | Disallows duplicates vs. Allows duplicates |
| Membership Test | O(1) average vs. O(n) |
| Use Case | Uniqueness, math operations vs. Sequential data, indexing |
Future Trends and Innovations
The future of set python lies in two directions: specialization and integration. As Python expands into domains like machine learning and real-time systems, the need for optimized set operations will grow. For instance, probabilistic data structures (e.g., Bloom filters) could be natively integrated into set python to handle approximate membership tests at scale. This would blur the line between traditional sets and advanced data structures, offering developers tools tailored to big data scenarios.Another trend is the rise of immutable sets (`frozenset`), which are gaining traction in functional programming paradigms. As Python’s ecosystem embraces immutability (e.g., for thread safety or memoization), set python variants that enforce immutability will likely see increased adoption. Additionally, JIT compilation in Python (via tools like PyPy) may further optimize set operations, reducing the overhead of dynamic hashing in performance-critical applications.
Conclusion
Python’s set is more than a data structure—it’s a testament to the language’s ability to balance simplicity with power. By leveraging hashing and mathematical operations, set python solves problems that would otherwise require verbose, error-prone code. Its impact spans from small scripts to large-scale systems, where efficiency and clarity are non-negotiable. As Python continues to evolve, the role of set python will only expand, particularly in fields where data uniqueness and speed are paramount.For developers, the takeaway is clear: set python isn’t just an alternative to lists—it’s a paradigm for writing cleaner, faster, and more maintainable code. Whether you’re deduplicating a dataset, performing set-based analytics, or optimizing an algorithm, understanding set python is a skill that separates good developers from great ones.
Comprehensive FAQs
Q: Can a set python contain mutable elements like lists or dictionaries?
A: No. Python’s set requires elements to be hashable, meaning they must be immutable (e.g., integers, strings, tuples). Mutable types like lists or dictionaries cannot be added to a set because their hash values change when modified.
Q: How does set python handle collisions in its hash table?
A: Python’s set uses open addressing to resolve collisions. If two elements hash to the same bucket, the set probes subsequent slots until an empty one is found. This method minimizes performance degradation while maintaining O(1) average-time complexity.
Q: What’s the difference between `set` and `frozenset` in Python?
A: A set python is mutable (elements can be added/removed), while `frozenset` is immutable (created once and cannot be altered). `frozenset` can be used as a dictionary key or stored in another set, whereas regular sets cannot.
Q: Are there performance trade-offs when using set python for large datasets?
A: While set python excels at O(1) operations, very large sets (millions of elements) may experience memory overhead due to hash table resizing. For such cases, consider alternatives like `frozenset` or external libraries optimized for big data (e.g., `pandas` for tabular data).
Q: Can I convert a list to a set python to remove duplicates?
A: Yes. Simply wrap the list in `set()`: `unique_items = set(original_list)`. This leverages the set’s deduplication property. Note that the result will be unordered, so use `dict.fromkeys()` if order preservation is needed.
Q: How does set python compare to NumPy’s `setdiff1d` for numerical data?
A: Python’s built-in set operations are generally faster for small to medium-sized datasets due to their optimized hash tables. However, NumPy’s `setdiff1d` (and similar functions) are more efficient for very large numerical arrays (millions of elements) because they use vectorized operations under the hood.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.