Understanding what does mean in Python: The Definitive Breakdown
Python’s `mean()` function is more than a simple arithmetic operation—it’s a foundational tool for data analysis, machine learning, and scientific computing. When developers ask "what does mean in Python", they’re often probing deeper than surface-level syntax: they want to understand how it integrates with libraries like NumPy, Pandas, and SciPy, and how it handles edge cases like missing data or non-numeric inputs. The function’s versatility extends beyond basic averages, influencing everything from financial modeling to image processing. Yet, its behavior can vary dramatically depending on the context—whether you’re working with a Pandas Series, a NumPy array, or raw Python lists. The ambiguity in "what does mean in Python" stems from this layered functionality, where the same term can refer to different implementations with distinct optimizations and quirks.
The confusion isn’t just semantic; it’s technical. For instance, Python’s built-in `statistics.mean()` is designed for small datasets with strict type checking, while NumPy’s `np.mean()` is optimized for large arrays of homogeneous data types. Even the term "mean" itself carries statistical weight—arithmetic mean, geometric mean, or harmonic mean—each requiring a different approach. Developers often overlook these distinctions, assuming all `mean()` calls behave identically. This oversight can lead to performance bottlenecks or incorrect results, especially in production environments where data integrity is critical. Understanding "what does mean in Python" isn’t just about memorizing syntax; it’s about grasping the underlying algorithms and their trade-offs.
The function’s role in Python’s ecosystem also reflects broader trends in computational thinking. As data volumes grow, the need for efficient mean calculations has driven innovations in parallel processing and memory management. Libraries like Dask and Vaex extend `mean()` functionality to handle datasets that exceed RAM capacity, demonstrating how Python’s statistical tools evolve alongside hardware limitations. Meanwhile, the rise of domain-specific languages (DSLs) in fields like bioinformatics or economics has led to specialized `mean()` implementations tailored to niche use cases. These developments underscore why "what does mean in Python" is a question with no single answer—it’s a gateway to exploring Python’s role in modern data science.
The Complete Overview of "What Does Mean in Python"
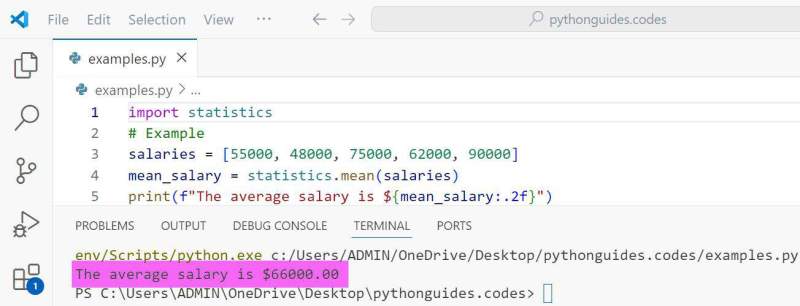
At its core, "what does mean in Python" refers to the calculation of the arithmetic average of a dataset, but the implementation varies across Python’s standard library and third-party packages. The simplest form appears in the `statistics` module, introduced in Python 3.4 as a dedicated tool for statistical computations. Here, `statistics.mean(data)` computes the sum of all elements divided by their count, but with critical safeguards: it raises `TypeError` for non-numeric inputs and `statistics.StatisticsError` for empty datasets. This strictness contrasts with NumPy’s `np.mean()`, which defaults to `float64` precision and silently ignores `NaN` values unless configured otherwise. The divergence highlights a fundamental choice in Python’s design philosophy: precision versus flexibility.Beyond basic arithmetic, "what does mean in Python" also encompasses weighted averages, where each element’s contribution is scaled by a factor. Pandas, for example, extends this concept with `Series.mean()`, which supports axis-specific calculations (rows vs. columns) and custom weights via the `skipna` and `numeric_only` parameters. These features reflect Python’s adaptability to real-world data, where missing values or mixed data types are common. Even the term "mean" itself can be ambiguous—geometric means (for multiplicative data) or harmonic means (for rates) require logarithmic transformations, which Python handles through `math.prod()` or custom loops. This multiplicity means that "what does mean in Python" isn’t a static concept but a dynamic one, shaped by the problem domain.
Historical Background and Evolution
The concept of calculating means predates Python itself, tracing back to 19th-century statistics. However, Python’s implementation of `mean()` was shaped by its design goals: readability, extensibility, and integration with scientific computing. The `statistics` module, added in Python 3.4, was a direct response to the lack of built-in statistical functions in earlier versions. Before this, developers relied on manual loops or external libraries like SciPy, which offered `scipy.stats.mean()` with additional statistical tests. This evolution mirrors Python’s broader trajectory—from a scripting language to a full-fledged data science platform.The rise of NumPy in the early 2000s marked a turning point. NumPy’s `np.mean()` wasn’t just faster; it was vectorized, meaning it operated on entire arrays without explicit iteration. This optimization became critical as datasets grew from thousands to millions of rows. Pandas, built atop NumPy, further democratized mean calculations by adding context-aware methods like `DataFrame.mean()`, which could aggregate across columns or rows with minimal syntax. Today, "what does mean in Python" encompasses a toolkit spanning from Python’s core to specialized libraries, each optimizing for different use cases—whether it’s real-time analytics or batch processing.
Core Mechanisms: How It Works
Under the hood, Python’s `mean()` implementations leverage different algorithms based on the data structure. The `statistics.mean()` function, for instance, uses a straightforward summation loop, which is simple but inefficient for large datasets. In contrast, NumPy’s `np.mean()` employs C-based optimizations, including loop unrolling and SIMD (Single Instruction, Multiple Data) instructions to process elements in parallel. This low-level efficiency is why NumPy’s `mean()` is the default choice for numerical computing. Pandas, meanwhile, inherits NumPy’s engine but adds overhead for metadata handling (e.g., column names, data types), which is necessary for tabular data but adds latency.Table of Contents
- The Complete Overview of "What Does Mean in Python"
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does `numpy.mean()` handle `NaN` values by default?
- Q: Can I compute a weighted mean in Python without external libraries?
- Q: Why does `statistics.mean()` raise an error for empty lists, while `numpy.mean()` returns `nan`?
- Q: How does Pandas’ `mean()` differ from NumPy’s when applied to a DataFrame?
- Q: Are there performance differences between `statistics.mean()`, `numpy.mean()`, and a Python loop?
- Q: Can I use `mean()` on non-numeric data in Python?
- Q: What is the most memory-efficient way to compute the mean for very large datasets?
The handling of edge cases further distinguishes these implementations. `statistics.mean()` fails explicitly on invalid inputs, while NumPy’s `np.mean()` provides options like `nan` propagation or filling missing values with `np.nanmean()`. This flexibility is critical in data pipelines where robustness outweighs strict correctness. For example, a financial application might use `np.mean()` with `skipna=True` to compute daily returns despite occasional `NaN` entries. The choice of `mean()` thus becomes a reflection of the application’s tolerance for errors and performance requirements.
Key Benefits and Crucial Impact
The ubiquity of `mean()` in Python stems from its role as a bridge between raw data and actionable insights. Whether calculating average user engagement metrics or training machine learning models, the mean provides a single-number summary that simplifies complex datasets. This reductionist power is why "what does mean in Python" is a question that resonates across industries—from healthcare (patient vital signs) to logistics (delivery times). The function’s integration with Python’s ecosystem further amplifies its impact, enabling seamless transitions from exploratory data analysis (EDA) to production-grade pipelines.Yet, the benefits extend beyond functionality. Python’s `mean()` implementations are designed for readability, reducing the cognitive load on developers. For example, `df['sales'].mean()` in Pandas is intuitive even for non-experts, lowering the barrier to entry for data analysis. This accessibility has fueled Python’s adoption in education and research, where clarity often outweighs raw performance. The trade-off between simplicity and speed is a defining characteristic of Python’s philosophy, and `mean()` embodies this balance.
"The mean is the most misunderstood statistic in data science—not because it’s flawed, but because its simplicity masks the complexity of the data it summarizes." — Hadley Wickham, Chief Scientist at RStudio (Python advocate)
Major Advantages
- Performance Optimization: NumPy’s `np.mean()` leverages vectorized operations, achieving near-native speeds for numerical data. For a dataset of 1 million elements, it can outperform Python loops by orders of magnitude.
- Flexibility in Data Types: Pandas’ `mean()` supports mixed data types (e.g., ignoring strings) and custom weights, making it adaptable to messy real-world datasets.
- Integration with Ecosystem: Functions like `mean()` in SciPy or TensorFlow extend to statistical testing and deep learning, creating end-to-end workflows without context switching.
- Memory Efficiency: Libraries like Dask’s `mean()` enable out-of-core computations, allowing analysis of datasets larger than RAM by processing chunks iteratively.
- Statistical Rigor: The `statistics` module enforces type safety and edge-case handling, ensuring correctness in critical applications like scientific research.

Comparative Analysis
| Implementation | Key Features |
|---|---|
| `statistics.mean()` | Strict type checking, raises errors on invalid inputs, best for small datasets or validation. |
| `numpy.mean()` | Vectorized, supports `dtype` and `axis` parameters, optimized for large arrays, handles `NaN` with options. |
| `pandas.Series.mean()` | Context-aware (e.g., `skipna`, `numeric_only`), integrates with DataFrame operations, ideal for tabular data. |
| `scipy.stats.mean()` | Includes statistical tests (e.g., confidence intervals), designed for hypothesis testing, less common for basic averaging. |
Future Trends and Innovations
As data grows more heterogeneous, the evolution of "what does mean in Python" will likely focus on two fronts: automation and specialization. Automated mean calculations—such as those powered by AI-driven data profiling tools—could reduce the need for manual parameter tuning (e.g., `skipna` settings). Meanwhile, domain-specific libraries may introduce custom mean variants, like robust means (resistant to outliers) or quantile-based means for skewed distributions. The rise of quantum computing could also redefine `mean()` operations, enabling exponential speedups for certain statistical computations.Another trend is the convergence of `mean()` with other aggregations (e.g., median, mode) into unified APIs. Tools like Polars or Vaex are already blurring the lines between these functions, offering a single `describe()` method that computes multiple statistics at once. This shift reflects a broader movement toward self-documenting data analysis, where the code itself explains the transformations applied. As Python solidifies its dominance in data science, "what does mean in Python" will continue to evolve—not as a static function, but as a dynamic interface to the ever-expanding frontier of computational statistics.

Conclusion
The question "what does mean in Python" reveals more than a technical detail—it exposes the layers of Python’s design philosophy. From the strict validation of `statistics.mean()` to the high-performance optimizations of NumPy, each implementation reflects a trade-off between correctness, speed, and usability. This diversity is Python’s strength, allowing developers to choose the right tool for the job, whether it’s a quick prototype or a production-grade analytics pipeline. As data science matures, the mean will remain a cornerstone, but its role will expand beyond simple averages into adaptive, context-aware computations.For practitioners, the takeaway is clear: "what does mean in Python" isn’t a single answer but a spectrum of possibilities. Mastery lies in understanding when to use each variant—whether it’s the precision of `statistics.mean()` for validation or the scalability of `np.mean()` for big data. The function’s journey from a basic arithmetic operation to a pillar of Python’s data ecosystem underscores why Python remains the language of choice for scientists, engineers, and analysts alike.
Comprehensive FAQs
Q: How does `numpy.mean()` handle `NaN` values by default?
NumPy’s `np.mean()` propagates `NaN` values by default, meaning if any element in the array is `NaN`, the result will also be `NaN`. To exclude `NaN` values, use `np.nanmean()` or set `nan_policy='omit'` in newer versions. This behavior differs from Pandas, where `Series.mean()` skips `NaN` by default unless `skipna=False` is specified.
Q: Can I compute a weighted mean in Python without external libraries?
Yes, but it requires manual implementation. For a list of values `data` and weights `weights`, use:
```python
weighted_mean = sum(x w for x, w in zip(data, weights)) / sum(weights)
```
Libraries like NumPy or Pandas provide built-in support via the `weights` parameter in `np.average()` or `Series.mean(weights=weights)`, but the manual approach works for simple cases.
Q: Why does `statistics.mean()` raise an error for empty lists, while `numpy.mean()` returns `nan`?
The `statistics` module prioritizes explicit error handling to prevent silent failures, which is critical for data validation. In contrast, NumPy follows IEEE floating-point standards, where operations on empty arrays return `NaN` (Not a Number) by convention. This difference reflects their intended use: `statistics.mean()` for small, curated datasets, and `np.mean()` for large-scale numerical computing where `NaN` propagation is often acceptable.
Q: How does Pandas’ `mean()` differ from NumPy’s when applied to a DataFrame?
Pandas’ `DataFrame.mean()` computes the mean along an axis (rows or columns) and returns a Series or scalar, depending on the axis. For example:
Q: Are there performance differences between `statistics.mean()`, `numpy.mean()`, and a Python loop?
For a dataset of 1,000,000 elements:
Q: Can I use `mean()` on non-numeric data in Python?
No, not directly. Python’s `mean()` functions require numeric inputs (e.g., `int`, `float`, NumPy types). Attempting to compute the mean of strings or mixed types will raise a `TypeError` in `statistics.mean()` or return `NaN` in NumPy/Pandas. To handle non-numeric data, preprocess it (e.g., convert strings to numeric codes) or use libraries like Pandas with `numeric_only=True` to filter out non-numeric columns.
Q: What is the most memory-efficient way to compute the mean for very large datasets?
For datasets larger than RAM, use out-of-core libraries like Dask or Vaex. Dask’s `mean()` processes data in chunks and aggregates results, while Vaex uses lazy evaluation to minimize memory usage. For example:
```python
import dask.dataframe as dd
ddf = dd.read_csv('large_file.csv')
mean_value = ddf['column'].mean().compute() # Computes in parallel
```
These tools avoid loading the entire dataset into memory, making them ideal for big data scenarios.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.