Understanding What Is Cached Data: The Hidden Workings of Digital Storage
When you visit a website, your device doesn’t just fetch the content in real time—it often stores a snapshot of it for later use. This unassuming process, known as what is cached data, is the backbone of faster load times, reduced server strain, and seamless user experiences. Yet despite its ubiquity, few understand how these temporary files function, why they linger on storage, or how they influence everything from privacy to system performance.
The concept of caching isn’t new; it’s a digital evolution of an age-old principle: storing frequently accessed information closer to where it’s needed. Whether it’s a browser saving a webpage’s HTML, a smartphone app preloading images, or a server maintaining a copy of database queries, what is cached data serves as an invisible layer between raw processing power and the user’s expectation of instant access. Without it, every interaction with technology would feel sluggish, as devices repeatedly re-fetched identical resources from their original sources.
But caching isn’t just about speed—it’s a balancing act. Too little caching leads to inefficiency; too much risks outdated data, storage bloat, or even security vulnerabilities. The trade-offs between performance and accuracy, between convenience and control, define why what is cached data remains a critical yet often overlooked aspect of modern computing.
The Complete Overview of What Is Cached Data
At its core, what is cached data refers to temporary copies of files, resources, or computations stored locally to minimize repeated access to slower, remote sources. This practice spans across systems—from individual devices to enterprise servers—and operates under a simple premise: if a piece of data is used frequently, storing it closer to the point of use reduces latency and conserves bandwidth. Whether it’s a browser caching a CSS file to avoid re-downloading it on every page visit or a cloud service caching API responses to handle spikes in traffic, the goal is consistent: optimize performance by reducing redundant operations.The term "cached data" encompasses a broad spectrum of implementations, each tailored to specific use cases. In web browsing, it might manifest as a browser cache storing images, scripts, or entire pages. On a server, it could be an object cache holding database query results to speed up dynamic content generation. Even mobile apps leverage caching to preload media or user preferences, ensuring smoother offline functionality. The common thread? All these mechanisms rely on what is cached data to bridge the gap between raw processing and real-time responsiveness.
Historical Background and Evolution
The origins of caching trace back to the early days of computing, where mainframe systems used core memory to store frequently accessed instructions and data. As hardware evolved, so did the need for more efficient data retrieval. The 1980s saw the rise of disk caching in operating systems, where buffers stored frequently used files to reduce disk I/O operations—a concept later adopted by databases and web servers. The World Wide Web’s explosive growth in the 1990s accelerated the demand for what is cached data, leading to the development of HTTP caching protocols like `Cache-Control` and `ETag`, which standardized how browsers and servers could store and validate cached resources.Today, caching has become a multi-layered discipline, with techniques ranging from client-side browser caching to distributed edge caching in content delivery networks (CDNs). The shift toward cloud computing and edge computing has further expanded its role, as providers like Cloudflare and Akamai use global caching infrastructures to deliver content with millisecond latency. Even emerging technologies like peer-to-peer (P2P) networks and blockchain leverage caching principles to optimize decentralized data access. The evolution of what is cached data mirrors the broader trajectory of computing: from centralized mainframes to decentralized, high-speed networks.
Core Mechanisms: How It Works
The mechanics of caching revolve around three key phases: storage, retrieval, and validation. When a resource—such as an image or a JSON file—is first requested, the system checks if a valid cached version exists. If not, it fetches the resource from its original source, stores a copy locally, and associates metadata like timestamps or expiration rules. Subsequent requests for the same resource are served from the cache until it expires or is invalidated, at which point the system repeats the fetch-and-store cycle.Table of Contents
- The Complete Overview of What Is Cached Data
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can cached data be harmful?
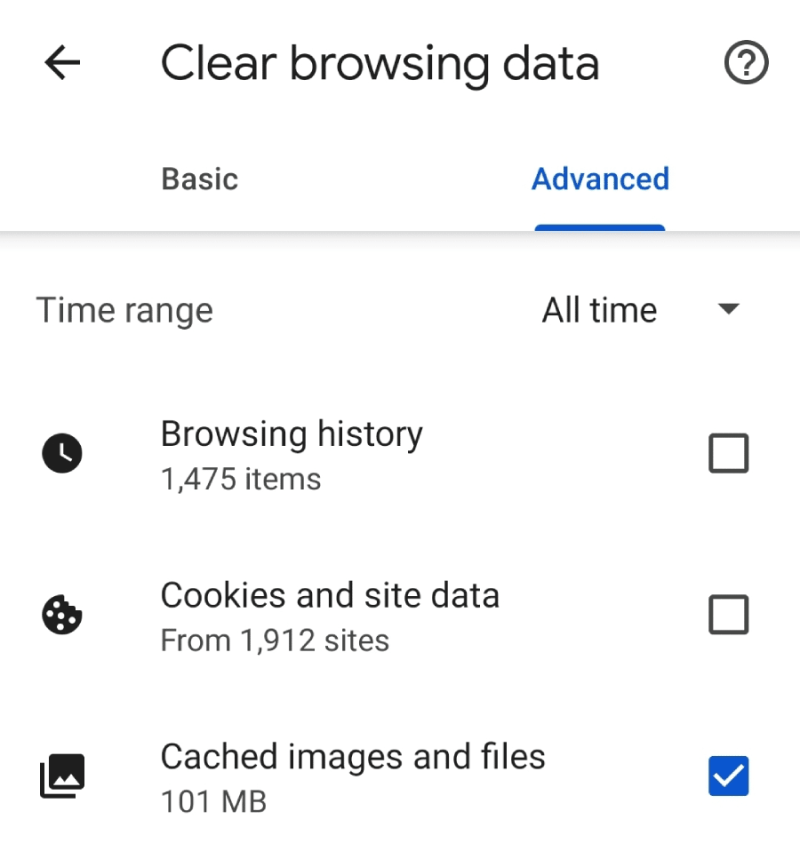
- Q: How do I clear cached data on my device?
- Q: Why does cached data sometimes cause issues with website updates?
- Q: Is cached data the same as a cookie?
- Q: How do CDNs use cached data differently than individual browsers?
- Q: Can cached data be used for tracking or surveillance?
Validation is where caching becomes nuanced. Systems use headers like `Last-Modified` or `ETag` to check if the cached version matches the original. If the server responds that the resource hasn’t changed, the cached copy is reused; otherwise, it’s discarded or updated. This process ensures that what is cached data remains fresh without unnecessary network overhead. Additionally, caches employ policies like Least Recently Used (LRU) or Time-to-Live (TTL) to manage storage limits, evicting older or less critical data when space is needed.
Key Benefits and Crucial Impact
The primary advantage of what is cached data is performance optimization. By reducing the need to re-fetch identical resources, caching slashes latency, lowers bandwidth usage, and lightens the load on servers. For end-users, this translates to faster page loads, smoother app interactions, and lower data consumption—critical factors in an era where mobile connectivity and user patience are both finite. Businesses benefit equally, as efficient caching reduces hosting costs and improves scalability during traffic surges.Beyond speed, caching plays a pivotal role in reliability. In distributed systems, where network failures or server outages are inevitable, cached copies act as fallback mechanisms, ensuring uninterrupted service. For example, a CDN might serve a cached version of a website even if the origin server is down, maintaining uptime. This redundancy is particularly valuable in global applications where geographic distance can introduce lag.
> "Caching is the art of making the expensive fast and the fast expensive." — Adapted from early distributed systems principles
Major Advantages
- Reduced Latency: Local retrieval of cached data eliminates round-trip delays to remote servers, often cutting load times by 50–90%.
- Bandwidth Savings: Repeated requests for the same resource consume less data, crucial for mobile users and high-traffic sites.
- Server Offloading: Caches absorb repetitive queries, reducing CPU and memory usage on origin servers.
- Improved User Experience: Smoother interactions, especially in offline or low-connectivity scenarios, enhance engagement.
- Cost Efficiency: Lower server costs and reduced infrastructure needs make caching a scalable solution for businesses.

Comparative Analysis
| Aspect | Browser Cache vs. Server Cache |
|---|---|
| Location | Browser cache resides on the user’s device; server cache is stored on the web server or CDN edge nodes. |
| Purpose | Browser cache improves individual user experience; server cache optimizes site-wide performance and reduces origin server load. |
| Lifetime | Browser caches are typically short-lived (hours to days); server caches can persist for weeks or until manually cleared. |
| Control | Users can clear browser cache manually; server cache management requires administrative access or CDN configurations. |
Future Trends and Innovations
The future of what is cached data is being shaped by advancements in edge computing, artificial intelligence, and decentralized networks. Edge caching, where data is stored closer to the end-user (e.g., on IoT devices or 5G-enabled routers), promises to further reduce latency by eliminating the need to backhaul requests to centralized servers. Meanwhile, AI-driven caching systems are emerging, using predictive algorithms to pre-fetch resources based on user behavior patterns—anticipating needs before they arise.Decentralized caching models, such as those powered by blockchain or IPFS (InterPlanetary File System), are also gaining traction. These systems distribute cached data across a network of nodes, enhancing resilience and reducing single points of failure. As quantum computing and high-speed networks like 6G become viable, caching will likely evolve to handle even more complex data structures, from real-time video streams to dynamic, personalized content. The next decade may see caching transcend its traditional role, becoming a cornerstone of autonomous, self-optimizing digital ecosystems.

Conclusion
What is cached data is more than a technical detail—it’s a fundamental pillar of modern digital infrastructure. From the first mainframe buffers to today’s global CDNs, caching has consistently delivered the twin benefits of speed and efficiency. As technology advances, its importance will only grow, particularly in an era where real-time interactions and data-intensive applications are the norm. Understanding how caching works, its trade-offs, and its evolving role is essential for developers, sysadmins, and end-users alike.The challenge lies in balancing its advantages with potential downsides, such as stale data or privacy concerns. As caching becomes more sophisticated, so too must the policies governing its use—ensuring that the invisible layer of temporary storage continues to serve as an enabler, not a hindrance, in the digital age.
Comprehensive FAQs
Q: Can cached data be harmful?
A: While cached data is generally benign, it can pose risks if not managed properly. Stale cached versions may serve outdated information, leading to incorrect actions (e.g., expired coupon codes or security patches). Additionally, sensitive data stored in caches—such as cookies or session tokens—could be accessed if a device is compromised. Always clear caches periodically and use privacy settings to mitigate risks.
Q: How do I clear cached data on my device?
A: The process varies by platform:
- Browsers: Use `Ctrl+Shift+Del` (Windows/Linux) or `Cmd+Shift+Del` (Mac) to open the Clear Browsing Data dialog. Select "Cached images and files" and choose a time range.
- Mobile Apps: Go to Settings > Storage > Cached Data and tap "Clear Cache." Some apps (like Facebook) have their own cache-clearing options.
- Operating System: On Windows, use Disk Cleanup; on macOS, empty the Trash after clearing browser caches.
Q: Why does cached data sometimes cause issues with website updates?
A: When a website updates its content (e.g., CSS, JavaScript, or HTML), browsers or proxies may continue serving cached versions to users. This can result in visual glitches, broken layouts, or failed functionality. Developers use techniques like cache-busting (appending version numbers to filenames) or setting short `Cache-Control` headers to force fresh fetches. Users can also hard-refresh (F5 or `Ctrl+F5`) to bypass the cache.
Q: Is cached data the same as a cookie?
A: No. While both are forms of stored data, they serve different purposes:
- Cached Data: Temporary copies of files (images, scripts) stored to speed up future requests.
- Cookies: Small text files stored by websites to track sessions, preferences, or user authentication.
Q: How do CDNs use cached data differently than individual browsers?
A: CDNs (Content Delivery Networks) employ a hierarchical caching strategy:
- Edge servers store copies of static assets (images, videos) globally, reducing latency for users worldwide.
- Dynamic content may be cached with shorter TTLs or only at the origin server level.
- CDN caches are managed centrally, allowing administrators to purge specific URLs or adjust caching rules site-wide.
Q: Can cached data be used for tracking or surveillance?
A: Indirectly, yes. While cached data itself doesn’t typically contain personal identifiers, it can be combined with other data points (e.g., IP addresses, timestamps) to infer user behavior. For instance, a sequence of cached requests might reveal browsing patterns. Privacy-conscious users should employ tools like VPNs, ad blockers, or browser extensions that limit cache storage. Laws like GDPR also regulate how cached data is handled in certain jurisdictions.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.