Decoding What Is N on Bar Graph: The Hidden Meaning Behind Data Visualization’s Most Critical Variable
Bar graphs are the silent architects of clarity in data-driven narratives. Yet, beneath their deceptively simple rectangular forms lies a variable so fundamental it often goes unnoticed: what is "n" on bar graph? This single symbol—whether labeled n, N, or count—serves as the linchpin between raw numbers and meaningful interpretation. It represents the sample size, the frequency of observations, or the cardinality of categories, all of which dictate how trustworthy a bar graph’s insights truly are. Ignore it, and you risk misreading trends; master it, and you unlock the ability to distinguish between noise and signal in any dataset.
The confusion around what "n" means in bar graphs stems from its dual role: as both a technical parameter and a narrative anchor. In academic research, it’s the denominator in confidence intervals; in business dashboards, it’s the justification for why a "high-performing" category isn’t just an outlier. Even seasoned analysts often conflate n with other metrics like mean or standard deviation, overlooking how it directly influences the graph’s vertical axis scaling, error bars, and comparative validity. The stakes are higher than most realize—misrepresenting n can skew decision-making, from marketing strategies to policy formulations.
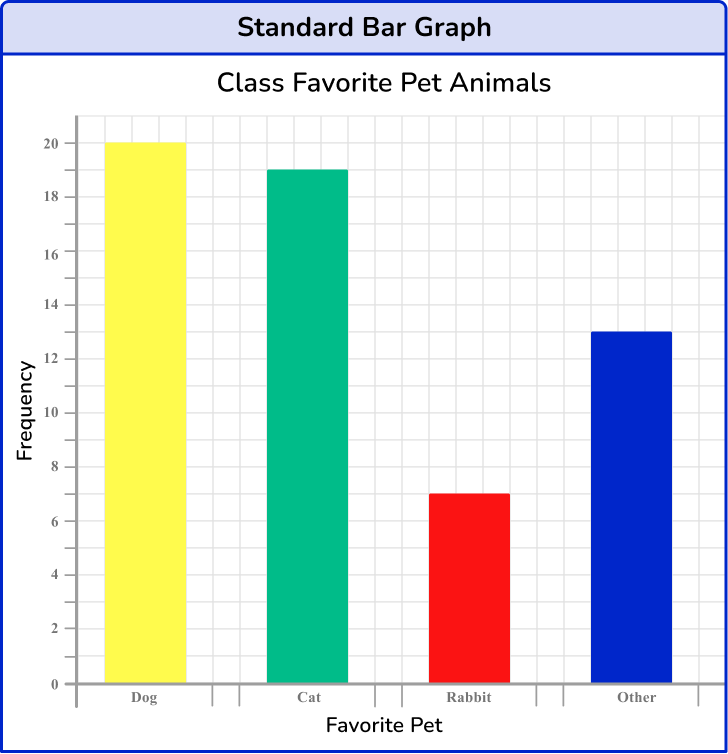
The Complete Overview of "What Is N on Bar Graph"
At its core, what "n" represents in bar graphs is the total number of observations contributing to each bar’s height. This could mean:The ambiguity arises because n isn’t always visually explicit. In some graphs, it’s implied by the axis labels (e.g., "Number of Customers"); in others, it’s buried in footnotes or legends. This omission forces interpreters to reverse-engineer the data’s reliability—asking whether a bar’s height reflects 100 respondents or 1,000. The answer to what "n" means in bar graph context thus hinges on the graph’s purpose: descriptive (showing distribution) or inferential (supporting hypotheses).
Historical Background and Evolution
The concept of n in data visualization traces back to the 19th century, when statisticians like Francis Galton and Karl Pearson formalized the relationship between sample size and representativeness. Early bar graphs, used in census reports and economic studies, often omitted n entirely, assuming the audience would infer it from context. However, as R.A. Fisher’s work on experimental design gained traction in the 1920s, the need for transparency grew. Fisher’s emphasis on statistical significance—where n directly impacts p-values—forced visualizations to confront their sample-size limitations.The modern era saw n evolve from an afterthought to a non-negotiable element in rigorous data presentation. Software like Excel, Tableau, and R now auto-generate n labels for categorical bars, but manual overrides persist in custom visualizations. The shift reflects a broader movement toward reproducible research, where what "N" stands for in bar graphs isn’t just a footnote but a validation criterion. Today, omitting n in a bar graph is akin to citing a source without a page number—technically possible, but ethically questionable.
Core Mechanisms: How It Works
The mechanics of n in bar graphs revolve around three critical functions:1. Axis Scaling: n determines whether the vertical axis shows counts (discrete) or percentages (relative). A bar labeled n=100 with a height of 40 might represent 40% of a sample, while the same height in an absolute graph would mean 40 units.
2. Error Margin Calculation: In graphs with confidence intervals (e.g., survey results), n dictates the width of error bars. A small n (e.g., 20) yields wider bars, signaling higher uncertainty—a visual cue often overlooked in casual analysis.
3. Comparative Validity: When comparing bars across groups (e.g., "Men vs. Women"), n ensures the comparison is fair. A bar for "Men" with n=500 and "Women" with n=50 shouldn’t be treated as equally representative without adjustment.
The interplay between n and what "n" means in bar graph data becomes especially critical in stacked bars, where segments may have different n values. Here, the graph must either:
Key Benefits and Crucial Impact
Understanding what "n" means in a bar graph isn’t just academic—it’s a practical safeguard against misinformation. In fields like medicine, where bar graphs depict clinical trial outcomes, an incorrect n could lead to life-altering decisions. Similarly, in marketing, a graph showing "Product A’s popularity" with an n=10 sample is meaningless, yet such errors persist in presentations. The impact of n extends beyond accuracy: it shapes audience trust. A graph labeled with n signals transparency; one without invites skepticism.Table of Contents
- The Complete Overview of "What Is N on Bar Graph"
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can a bar graph have different "n" values for each bar?
- Q: What’s the difference between "n" and "N" in bar graphs?
- Q: How does "n" affect the height of a bar in a percentage graph?
- Q: Are there cases where "n" shouldn’t be displayed?
- Q: How can I check if a bar graph’s "n" is reliable?
The psychological weight of n is further amplified in public discourse. During the COVID-19 pandemic, bar graphs comparing case counts across regions often omitted n, leading to debates over whether differences were statistically significant or mere artifacts of varying sample sizes. The lesson was clear: what "N" represents in bar graphs isn’t just a technicality—it’s a cornerstone of credibility.
> "A graph without 'n' is like a map without a scale: you can see the shapes, but you’ll never know the distances." — Edward Tufte, The Visual Display of Quantitative Information
Major Advantages
- Statistical Rigor: Explicit n values allow readers to calculate margins of error or perform post-hoc tests (e.g., chi-square) without accessing raw data.
- Audience Clarity: Labels like n=1,000 immediately contextualize a bar’s height, reducing cognitive load for non-experts.
- Error Prevention: Highlighting n forces creators to question whether their sample is representative (e.g., n=5 for a national trend is inherently flawed).
- Reproducibility: In academic or regulatory settings, n serves as a metadata checkpoint, ensuring others can replicate or challenge the analysis.
- Ethical Compliance: Many journals and institutions (e.g., ICMJE guidelines) mandate n disclosure to prevent data cherry-picking or selective reporting.

Comparative Analysis
| Aspect | With Explicit "n" Labeling | Without "n" Labeling |
|---|---|---|
| Interpretability | High—readers can assess scale and reliability. | Low—ambiguity leads to misinterpretation (e.g., assuming n is consistent across bars). |
| Statistical Validity | Supports hypothesis testing (e.g., t-tests, ANOVA). | Invalidates comparisons; p-values cannot be trusted. |
| Use Cases | Research papers, clinical trials, policy reports. | Informal presentations, exploratory dashboards (risky for high-stakes decisions). |
| Software Defaults | Excel: "Value" axis shows counts; Tableau: Auto-labels n in categorical charts. | Custom graphs (e.g., hand-drawn or poorly configured tools) often omit n. |
Future Trends and Innovations
The future of n in bar graphs will be shaped by two opposing forces: automation and transparency demands. As AI-generated visualizations proliferate (e.g., Google Looker Studio’s auto-charts), n will likely become default-labeled in most tools, reducing human error. However, this also risks over-reliance on algorithms, where n is treated as a checkbox rather than a critical think-through.Conversely, open-data movements and regulatory scrutiny (e.g., EU’s AI Act) will push for granular n disclosure, including:

Conclusion
The question what is "n" on bar graph isn’t just about labels—it’s about the contract between data and its audience. A graph without n is like a contract without signatures: legally dubious and prone to exploitation. As data literacy becomes a global competency, the stakes for n transparency will only rise. The graphs of tomorrow may auto-calculate n’s impact on reliability, but the principle remains unchanged: what "N" means in bar graphs is the difference between insight and illusion.For creators, the takeaway is simple: never let n be an afterthought. For consumers, it’s a call to action: demand n in every graph you encounter. The variable may be small, but its influence is monumental.
Comprehensive FAQs
Q: Can a bar graph have different "n" values for each bar?
A: Yes, but it requires explicit labeling. For example, a stacked bar might show n=100 for "Group A" and n=50 for "Group B." Without labels, comparisons are invalid. Tools like R’s ggplot2 allow custom n annotations per bar.
Q: What’s the difference between "n" and "N" in bar graphs?
A: Conventionally, lowercase n refers to sample size per category, while uppercase N denotes the total sample size (e.g., N=500 total respondents, n=200 per demographic). Some fields (e.g., psychology) use N for total n for subgroups.
Q: How does "n" affect the height of a bar in a percentage graph?
A: In percentage graphs, n doesn’t directly alter bar height—100% always equals the same visual length. However, n determines the stability of the percentage: a 50% bar with n=10 is far less reliable than one with n=1,000. Error bars (if shown) will reflect this uncertainty.
Q: Are there cases where "n" shouldn’t be displayed?
A: Rarely, but in highly aggregated data (e.g., "Global GDP by Region"), n may be implied (e.g., all countries). However, even here, footnote disclosure is best practice. Omitting n in low-n datasets (e.g., n<30) is always unethical.
Q: How can I check if a bar graph’s "n" is reliable?
A: Ask three questions:
1. Is n disclosed? If not, assume bias or error.
2. Is n large enough? Rule of thumb: n≥30 for means, n≥5 per category for proportions (though context matters).
3. Does n vary? If bars represent subgroups, ensure n isn’t disproportionately small for any category.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Gouv.